Preventing Scope Creep When AI Features Depend on Live Web Data
Define data pipeline ownership early to avoid cascading hidden costs in live-web AI features.
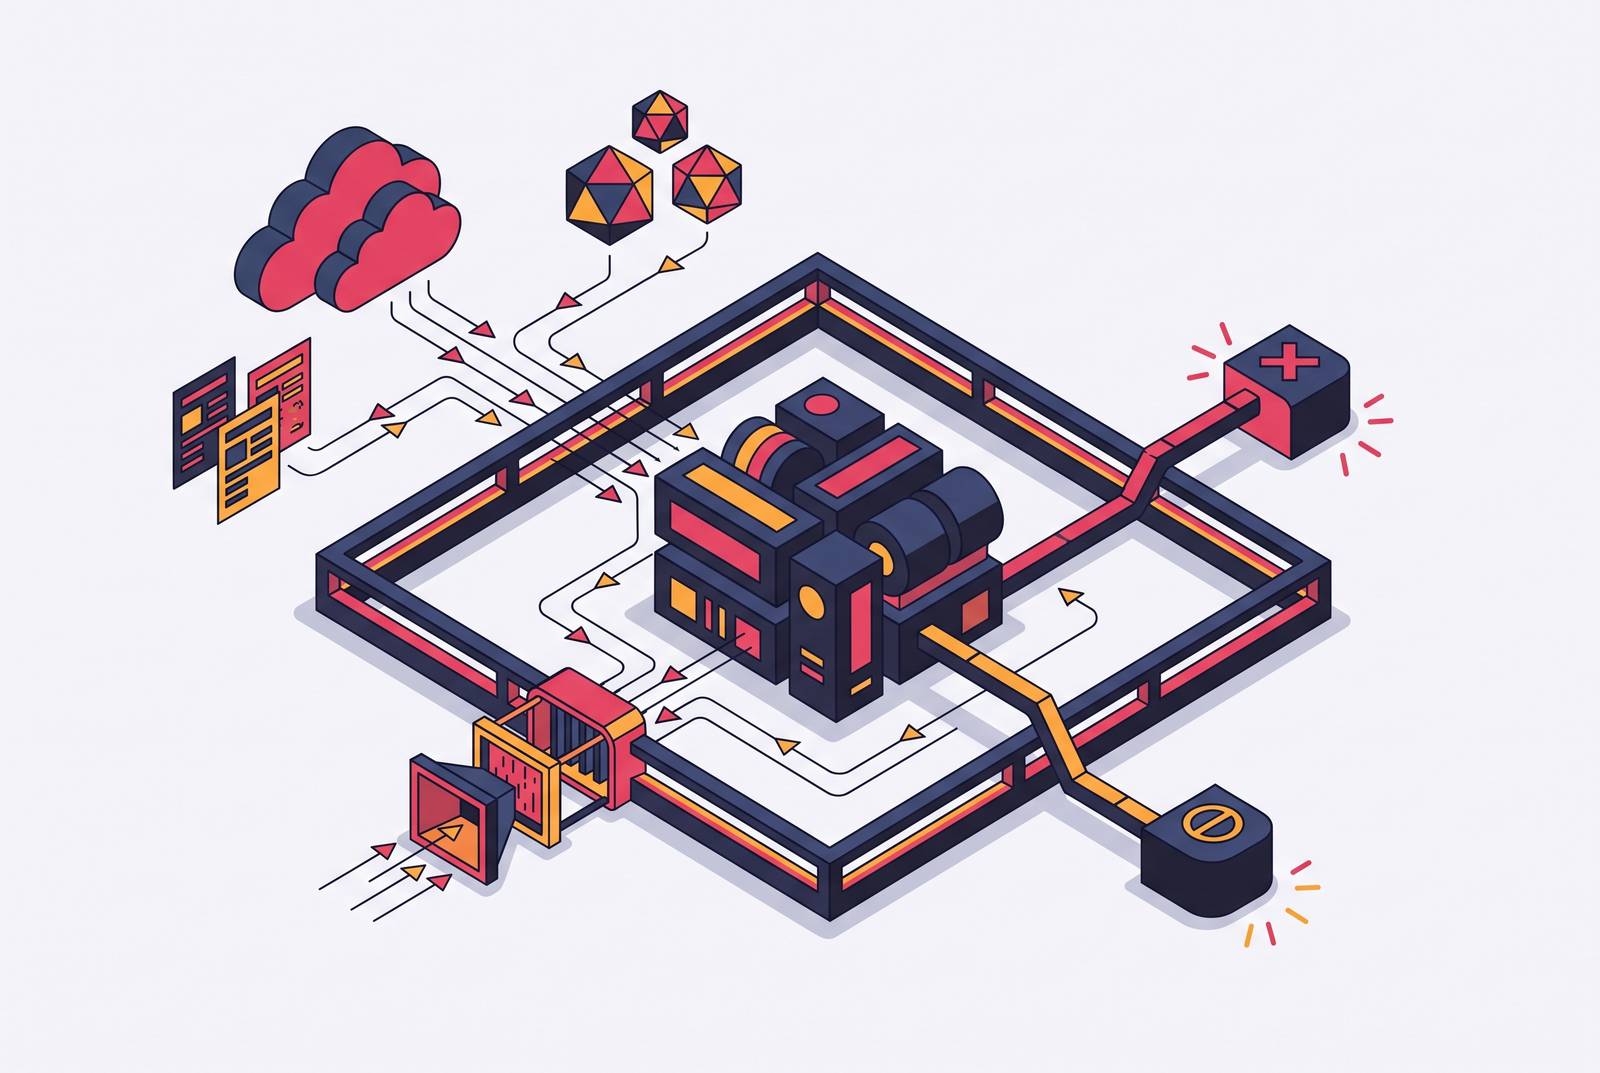
Scope creep on live-web AI features almost always traces back to one decision made too late: who owns the data pipeline, and how the team handles freshness. Teams that treat the retrieval layer as a first-class design choice, rather than a detail to sort out mid-build, end up with naturally bounded features. Everyone else ends up renegotiating the project every other week.
A Kalvium case study, drawn from an account of 30 AI projects, describes a compliance-checker build where the founder saw a working demo in week two and asked for empathy scoring to be added on top. That request wasn't unreasonable. A working demo changes what a client believes is possible faster than any timeline can absorb new asks. Live-web AI features make this worse than almost any other category of software, because the data layer behind them is invisible in the demo and explosive in the build. The client sees a fast, accurate, current answer. They don't see the JavaScript rendering, the anti-bot handling, the content cleaning, or the freshness logic that made that answer possible.
47Billion's 7Seers team ran into this directly. Wrong answers on live topics looked like a model problem at first. The actual cause was the pipeline feeding the model, and fixing it took far more engineering effort than the original feature estimate had assumed. The scope threat on live-web features is never one large, visible addition, but a cascade of smaller, hidden sub-projects, JavaScript rendering, CAPTCHA handling, rate limiting, IP rotation, content cleaning, token budget management, each a real engineering project in its own right, each one appearing only after the feature is already underway.
How the retrieval layer becomes a hidden scope dependency
Scope expands on these features for a specific structural reason: teams treat the retrieval layer as an implementation detail to figure out later, rather than a design decision that shapes everything built downstream of it.
The common pattern looks reasonable at the outset. A team prototypes with a static set of documents, ships something that works in the demo, and then bolts on live retrieval mid-sprint once the knowledge base goes stale. Each step in that sequence is reactive. None of it was designed.
The shift from static to live retrieval shows how much is actually being swapped out. Static RAG needs an ingest step, a chunking step, an embedding step, a storage step, and then a continuous re-indexing pipeline to keep the whole thing current. Live retrieval replaces that entire sequence with a single query-time web call. That sounds like a simplification, and in some ways it is. But the two architectures carry fundamentally different ownership models, cost structures, and latency profiles. A team that starts with static ingestion and pivots to live retrieval mid-sprint is changing who owns freshness, how latency gets budgeted, and what the system does the moment a target page changes its structure.
That dependency gets more dangerous once agents enter the picture. When an agent can direct its own web retrieval, an undefined data dependency doesn't stay contained. It expands in step with the agent's autonomy, because the agent will follow any retrieval path that looks useful, whether or not anyone scoped it.
Three technical realities that make retrieval scope hard to estimate
Retrieval scope is hard to estimate even for experienced teams, because web scraping in 2026 contains three compounding technical traps that only reveal themselves once the work is already underway. These traps appear in sequence, not all at once, which is part of why mid-sprint course corrections on these features get so expensive.
The first trap is rendering. JavaScript rendering is non-negotiable on most modern sites, and it's rarely scoped into the original estimate. Full browser automation through tools like Playwright solves the rendering issue, but it adds overhead and draws the attention of anti-bot systems, which the original scope never accounted for.
Once rendering and anti-bot handling are solved, a second trap appears: the content itself. Raw HTML is structurally harmful to large language models, not just inefficient to process. A typical web page is mostly noise relative to its actual content: navigation menus, ads, sidebars, and cookie banners all consume tokens without adding signal. The model has no way to tell boilerplate from substance. It treats a sidebar link to a three-year-old article as information equal in weight to the article it sits beside, and the resulting output looks incoherent in a way that reads like a model failure but is actually a pipeline failure. Turning raw HTML into clean Markdown or structured JSON that an LLM can use well is its own engineering problem, a one-line post-processing step tacked onto the end of a pipeline is not enough.
The third trap appears later, often after the feature has shipped, in selector maintenance. CSS selectors and XPath expressions break whenever a site redesigns, and dynamic class names combined with deeply nested divs make that kind of breakage painful to track down and impossible to predict. Every redesign by a data source becomes an unscheduled sprint item for whichever team maintains the scraper, scope that was never estimated because it arrives on someone else's timeline, not the team's own. LLM-based extraction, where a JSON schema defines the fields to pull and the model extracts them regardless of page layout, resists this kind of breakage structurally. But it comes with its own cost: more inference per page, slower throughput. That trade-off needs to be decided at design time. Discovering it in production is how a one-time engineering cost turns into ongoing debt.
Treating the retrieval layer as a first-class design decision
The fix for all three traps is the same fix: define data pipeline ownership before the feature gets built, not after. A defined data contract keeps undefined fields and undefined responsibilities from silently appearing in downstream systems.
That data contract has three parts, and all three need to be settled early. First, scope: what the pipeline actually retrieves. Second, a freshness SLA: how current that data needs to be. Third, ownership: who is responsible for the pipeline when something breaks.
Schema-first extraction is what makes the scope boundary enforceable rather than aspirational. When a JSON schema defines what the pipeline extracts, an undefined field has no path into the downstream system. The schema itself is the boundary.
The freshness SLA does similar work for timing. A feature specified only as "real-time," with no latency budget attached, is a scope problem waiting to detonate. Web retrieval adds meaningful latency compared to vector retrieval, which runs under 100 milliseconds, so that gap has to be budgeted before the feature is built. Ownership matters most at the moment of failure: if a target site changes its structure, someone needs to already be assigned to fix the pipeline, and if a source moves behind a paywall, someone needs to already be assigned to decide the alternative. Leaving those questions open at design time guarantees they become unplanned sprint work later.
Defining these three things early creates a natural scope boundary around the whole feature.
Choosing between static retrieval, live retrieval, and hybrid before a line of code is written
The retrieval mode, static, live, or hybrid, is the first and most consequential pipeline decision a team makes, and it has to happen before any feature gets built on top of it. This choice is effectively irreversible once a sprint is underway: it sets the pipeline's cost model, its latency profile, and who owns its maintenance from day one.
Static retrieval, built on a vector store, fits stable, proprietary knowledge: HR policies, product documentation, internal wikis, the kind of content that changes rarely and that the team already controls. It fails the moment freshness needs to be measured in days rather than months. A RAG system grounded in week-old government policy data gives wrong answers, and a job-matching engine pulling stale listings misrepresents the actual market to the people using it. Staying current under a static architecture means running continuous ingestion: monitoring sources, re-crawling updated pages, re-chunking, re-embedding, updating the index, and handling deletions, infrastructure that most teams quietly fall behind on.
Live retrieval, a query-time web fetch, removes the ingest, embed, and store stages for web content entirely. There's no vector database to maintain and no re-indexing pipeline to keep running, because every query pulls current information directly. The cost is latency. Web retrieval takes meaningfully longer than vector retrieval running under 100 milliseconds, so a latency budget has to be set before the feature is specified. Without that budget, "real-time" quietly becomes an unscoped requirement that nobody agreed to. Live retrieval fits queries about prices, regulations, news, or any named entity whose status changes frequently.
Hybrid retrieval is the production default for complex systems. Many production systems combine a static vector store for proprietary or stable content with live web retrieval for anything current and external, running a two-stage flow: check the local store first, then route to live retrieval only if the query actually needs fresh data. That routing decision, whether a given query needs fresh data, has to be designed explicitly, through a query-term heuristic or a lightweight classifier, and the design of that router is itself scope-defining, because it determines exactly which queries incur live retrieval's cost and latency. One more distinction belongs in this conversation at requirements time: deep research, an adaptive search loop against the live web where each result shapes the next query, is a different problem from RAG, which answers from a known knowledge base. Treating the two as interchangeable at the requirements stage is a common and avoidable source of scope expansion.
Whichever mode a team picks, documenting that choice in Sprint 0 is what constrains the feature set that gets built afterward.
Consolidated web data infrastructure and the data contract
Consolidating retrieval behind a single, well-defined API turns the data contract from a policy into a structural fact, because the API's interface becomes the scope boundary. Whatever the API doesn't return, the feature simply cannot use.
Building retrieval in-house means owning every layer of that stack: JavaScript rendering, content cleaning, anti-bot handling, rate limiting, and the ongoing maintenance debt every time a target site changes its structure. Each of those layers is an unscoped sub-project waiting to surface on somebody's sprint board.
A purpose-built web data API returns structured, LLM-optimized content, clean Markdown or structured JSON, instead of raw HTML. The cleaning and parsing work moves down to the infrastructure layer, off the feature team's plate entirely. Declaring the retrieval layer as a dependency with a defined interface gives it an owner, a contract, and a lifecycle, the same discipline that keeps scope creep out of any other kind of integration.
None of this is free, and the trade-offs deserve to be stated. API-first development introduces a vendor dependency. Rate limits become real system constraints rather than theoretical ones. Per-request pricing requires cost forecasting at design time, before the feature ships, not after usage climbs. These constraints are visible constraints, written into the data contract from the start. They don't ambush a team mid-sprint the way an undocumented scraper failure does.
Website change detection as a pipeline design question, not a monitoring afterthought
A feature that depends on live web data also depends, implicitly, on knowing when that data changes. Teams that defer this question with "we'll set up monitoring later" are leaving a class of maintenance work unscoped and unowned, and it surfaces as unplanned work the first time a source changes without warning.
Two different models handle this, and the choice between them is itself a scope boundary. A pull-based approach checks a source on a schedule and sends a diff, typically by email, suited to workflows where a person reviews the change and decides what to do with it. A push-based approach instead delivers a structured JSON payload directly to a system endpoint the moment a change is detected, suited to automated pipelines where the change triggers a downstream action without a human in the loop. Choosing between them fixes whether change handling lives as a human workflow or as a data pipeline event, and that choice needs to happen at design time, because it defines both ownership and scope.
Olostep's Monitors endpoint illustrates what this looks like as an API primitive rather than a bolted-on monitoring script. A monitor gets created from a natural-language query, with schedules configurable down to every 10 minutes, alerts delivered by webhook, and structured diffs returned through a changeTracking format, with no custom comparison logic required. Handled this way, a website change becomes a defined event inside the pipeline, scoped, owned, and budgeted before the feature ever reaches a sprint review.
Sources
- Web data for scraping developers in 2026: AI fuels the agentic future
- Scope Creep in AI Projects: How to Manage It (2026)
- AI Web Scraping Agent: What Holds Up in Production | Zentor Blog
- Best AI Web Scraping Tools for LLM and RAG Pipelines in 2026
- Building a RAG Pipeline on Live Web Data - Joinmassive
- Just One More Round: Scope Creep in the Age of AI Agents - DEV Community