Connecting a Crawl-and-Index API to Pinecone or LlamaIndex Without Custom Scrapers
Clean web content feeds vector databases better than raw HTML scraped in-house.
A Pinecone index can be live and a LlamaIndex query engine can be wired up and tested, and the pipeline still won't work, because nothing clean has been put into it yet. The bottleneck in most AI pipelines is an unglamorous layer underneath both the model and the vector store: getting live web content off the page and into a form a retriever can use.
Custom scrapers as the wrong starting point for a RAG pipeline
Before any retrieval happens, a team building RAG over web content has to solve a pile of problems that have nothing to do with language models: rendering pages that load their content through JavaScript, stripping out navigation bars and ad blocks and footer links, converting whatever's left into normalized text, shaping that text so it splits into clean chunks, and then watching all of it for pages that have gone stale since the last crawl.
Raw HTML can't go into an embedding model or a vector database as-is. The markup, the nav menus, the ad slots all get embedded right alongside the actual content, and they pollute the index with noise that shows up in search results later. Most of the bugs a team fights for months, and most of the ongoing maintenance bill, trace back to this one cleaning step.
If a retrieval layer is fed stale or dirty source material, no amount of prompt tuning can fix it. A model can be prompted carefully and still hand back a wrong or outdated answer if the documents behind it are three months old or full of HTML junk. Large language models have a knowledge cutoff baked into training, so they can't know about last week's policy change or a page published yesterday unless a retrieval layer reaches live content. RAG only works if that retrieval layer supplies content that is both current and clean, because missing either one degrades the model's output no matter how good the model itself is.
Teams often resist handing this step to a third party because building the scraper in-house means full control over how the content gets cleaned. The cleaning step is exactly where the bugs live, and it also keeps generating work months after launch: a site redesign breaks the extraction rules, a new ad network introduces new boilerplate, a JavaScript framework update changes how content renders. If a managed crawl API returns clean Markdown instead of raw HTML, you remove that whole category of maintenance. A team no longer has to own and debug the scraping and cleaning logic forever.
What a crawl-and-index API replaces in the pipeline
A full pipeline for RAG over web content runs through six stages: map the site, crawl the pages, chunk the text, embed the chunks, write vectors to a database, and query through a retriever. A crawl-and-index API that hands back clean Markdown owns the first two stages outright, and it delivers the output right at the boundary where chunking starts.
Specifically, the API takes on URL routing and site mapping (figuring out which pages exist and how they link together), rendering JavaScript so dynamic content actually shows up in the output, pulling the real content out from around the navigation and ads, stripping boilerplate, and converting everything into Markdown that keeps headings and document structure intact. That output can go straight into a chunker. No second cleaning pass is needed.
What's left for the developer: splitting the Markdown into nodes, picking an embedding model, writing the resulting vectors into a store, and wiring up a retriever on top. LlamaIndex and Pinecone both have mature, well-documented abstractions for every one of those steps, which was never the hard part to begin with.
The same pattern extends past prose. Some crawl APIs accept a JSON schema on an extraction endpoint and return typed, structured fields instead of Markdown, which matters when the retrieval layer needs a price, a publish date, or an author name rather than a paragraph of text to search over.
That handoff point, clean Markdown landing in the developer's hands, is where the LlamaIndex integration actually starts.
Setting up the LlamaIndex side: packages, versions, and the dependency traps to avoid
Three packages need to be installed, under the right names: llama-index-core (currently at 0.14.24), llama-index-vector-stores-pinecone (currently at 0.7.1), and pinecone. The package named pinecone-client is deprecated; installing it instead of pinecone is a common and avoidable mistake.
Python 3.10 or later is required across the board. LlamaIndex 0.14.x dropped support for Python 3.9, and Pinecone's SDK, now at v9.x, enforces the same 3.10 floor.
Tutorials still circulating show initializing Pinecone with pinecone.init(...). That pattern is dead. The current client gets instantiated as Pinecone(api_key=...).
Version conflict worth checking before deployment: Pinecone's v9 SDK moved control-plane operations to namespaced methods, so index creation runs through
pc.indexes.create()and data-plane access runs through lowercasepc.index(). The older flat methods,pc.create_index()andpc.Index(), still appear in official examples and in the LlamaIndex integration reference. Those are v8-style calls. Pinecone v9 keeps them working as deprecated aliases rather than removing them outright, but as of August 2026 it isn't confirmed whether llama-index-vector-stores-pinecone 0.7.1 has been updated for the v9 method names. Pin exact versions in requirements.txt and check the installed SDK version against whichever method names get used, rather than copying a code sample without checking which SDK generation it targets.
A dimension mismatch between the embedding model and the Pinecone index doesn't throw an error. It returns zero results or irrelevant ones, silently, which makes it one of the harder bugs to trace back to its source. Set and check the dimension explicitly before the index gets created.
Credentials belong in environment variables instead of in code. You load PINECONE_API_KEY and PINECONE_INDEX_NAME through load_dotenv(), and you keep both values out of source control.
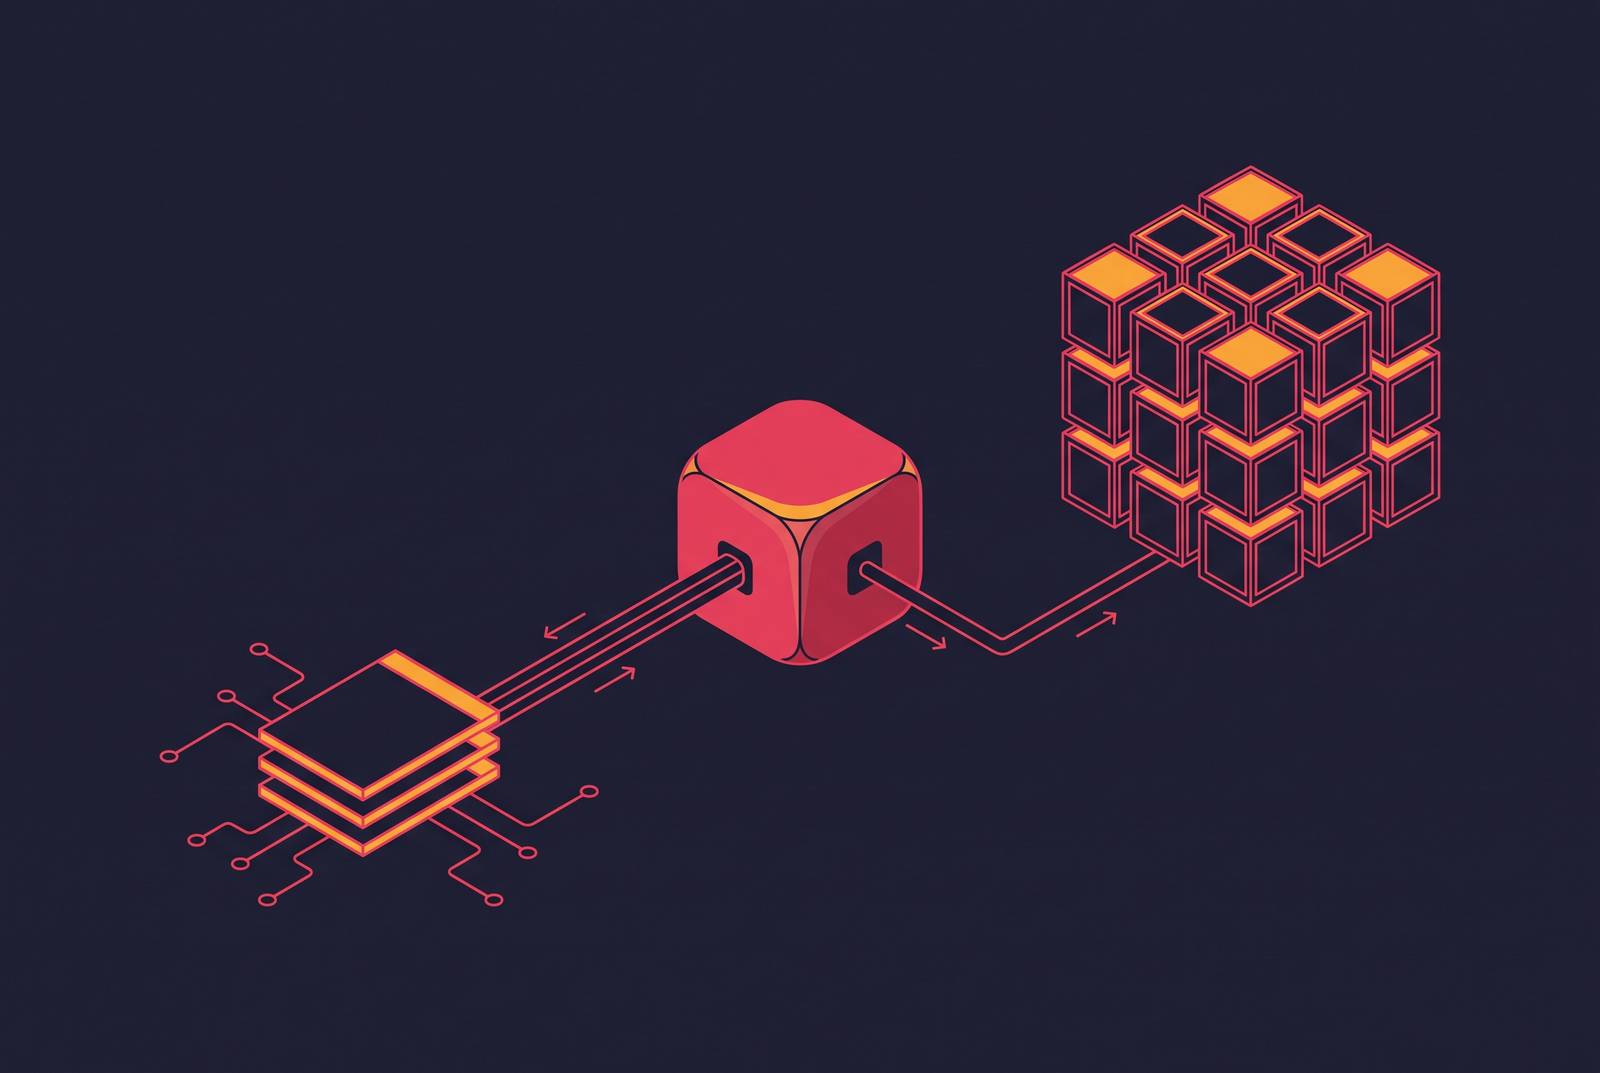
The resulting topology runs: the application calls LlamaIndex for ingestion and querying, LlamaIndex talks to PineconeVectorStore, and PineconeVectorStore writes to and reads from the actual Pinecone index, serverless or pod-based. For anything that moves faster than a static guide can track, the official LlamaIndex and Pinecone documentation stays the better reference than any tutorial.
Feeding crawl output into LlamaIndex: from Markdown to indexed nodes
Markdown coming out of a crawl API keeps its heading structure intact, and that structure gives LlamaIndex's node parser real boundaries to split on instead of cutting text at an arbitrary token count with no regard for where one idea ends and the next begins.
The workflow runs in a straight line. You call the crawl API with a target URL or an entire domain. Get back clean Markdown, one document per page. You wrap each page as a LlamaIndex Document object, and you carry the source URL along as metadata. You run the set of documents through SentenceSplitter to produce the nodes that get embedded and indexed.
Two fields in that metadata matter past the first run: the canonical URL and a content hash. Both get used later during incremental re-indexing, when stale vectors need replacing without re-crawling an entire site from scratch.
Node IDs deserve attention too. When content from multiple crawled domains gets merged into one index, autogenerated IDs on identical or near-identical chunks can collide, and that collision causes silent data loss in Pinecone, not an error message. Setting explicit, source-aware node IDs per document avoids it.
Where the crawl API runs schema-driven extraction instead, for product pages, pricing tables, or company data, the response comes back as structured JSON. Those fields map onto LlamaIndex Document metadata directly, or into structured node payloads, so they don't get treated as prose to chunk.
One more decision locks in early and stays locked: the embedding model chosen determines the vector dimension the Pinecone index gets created with. Fix that choice before the index exists. Changing the embedding model later means recreating the index from scratch and re-embedding every chunk.
Settings.embed_model and Settings.llm in LlamaIndex apply globally across the running process, affecting every index and query operation that runs after they're set. Switching embedding models partway through a pipeline requires calling Settings.reset() explicitly, or the old model quietly keeps getting used somewhere downstream.
Writing nodes to Pinecone and wiring the LlamaIndex query engine
Once nodes exist, they get written to Pinecone through a PineconeVectorStore wrapped in a StorageContext, and the choices made at this step decide how good the answers coming back actually are.
Pinecone is a remote service, so every query has to make a network round trip. If a corpus is small enough to fit in memory, an in-process vector store adds no latency, and it costs nothing monthly. Pinecone earns its place once corpus size, concurrent query load, or uptime requirements go past what an in-process store can handle.
Three retrieval settings do most of the work in determining answer quality, and similarity_top_k controls how many nodes come back per query. The similarity score threshold sets how close a match has to be before it counts: set it too low and irrelevant chunks get pulled in, set it too high and relevant chunks phrased differently from the query get missed. A starting range of 0.70 to 0.80 works for most document corpora. Hybrid search, combining vector similarity with BM25, helps on queries that depend on an exact technical term or an identifier a pure embedding match might miss.
Metadata filters in Pinecone let a retriever scope its search to a specific source domain or a specific crawl date range, and that matters once an index spans more than one crawled site and a query needs to stay within one of them.
Pinecone caps how much metadata can be stored per vector. A retrieval strategy that calls for stashing full document text or long JSON blobs in metadata will hit that cap at the Pinecone API level, not inside LlamaIndex, so it's worth sizing metadata payloads against that limit before building the strategy around it.
Pinecone isn't the only reasonable choice at this stage. Teams running corpora under tens of millions of chunks, without yet needing Pinecone's managed replication, can run pgvector inside the same PostgreSQL instance many teams already operate, getting vector similarity search alongside ordinary SQL in one place. The pipeline that started with a crawl API returning clean Markdown ends here, with nodes queryable through whichever store matches the corpus's actual scale.