Managed Scraping APIs vs. Self-Hosted Headless Browsers for Early-Stage Teams
Self-hosted scrapers cost far more in maintenance than managed APIs save upfront.
Pulling data off the web used to be a simple job. Now it sits at the center of a resource problem that every early-stage team has to solve before it can build anything else. Most production sites today run on React, Vue, or Angular, and those frameworks lean on client-side rendering, lazy-loaded content, and data that only shows up after an API call fires in the browser. A plain HTTP request to one of these pages returns an empty shell. A real browser has to load and run the page before there's anything to read. Scraping now starts with browser automation, not a simple fetch.
At the same time, the sites on the other end have gotten better at spotting that automation. Behavior-based bot detection, IP reputation scoring, strict rate limits, and browser fingerprinting used to guard only the biggest platforms. Those defenses are now standard on mid-size sites too. A scraper that runs clean in a test environment can fail silently once it hits production, and the failure often won't announce itself. It just stops returning the data you need.
None of this would matter as much if demand for live web data weren't climbing at the same time. AI pipelines, RAG systems, and agentic workflows all need fresh, structured content pulled straight from the web, because a model's training data has a cutoff and can't tell you what changed last week. Small teams are hitting a harder scraping environment at the exact moment their products depend on getting it right.
What the build-vs-buy decision is for an early-stage team
The choice between a managed scraping API and a self-hosted headless browser is a question of which ongoing costs a team is willing to carry, and for how long, not which tool performs better on a benchmark.
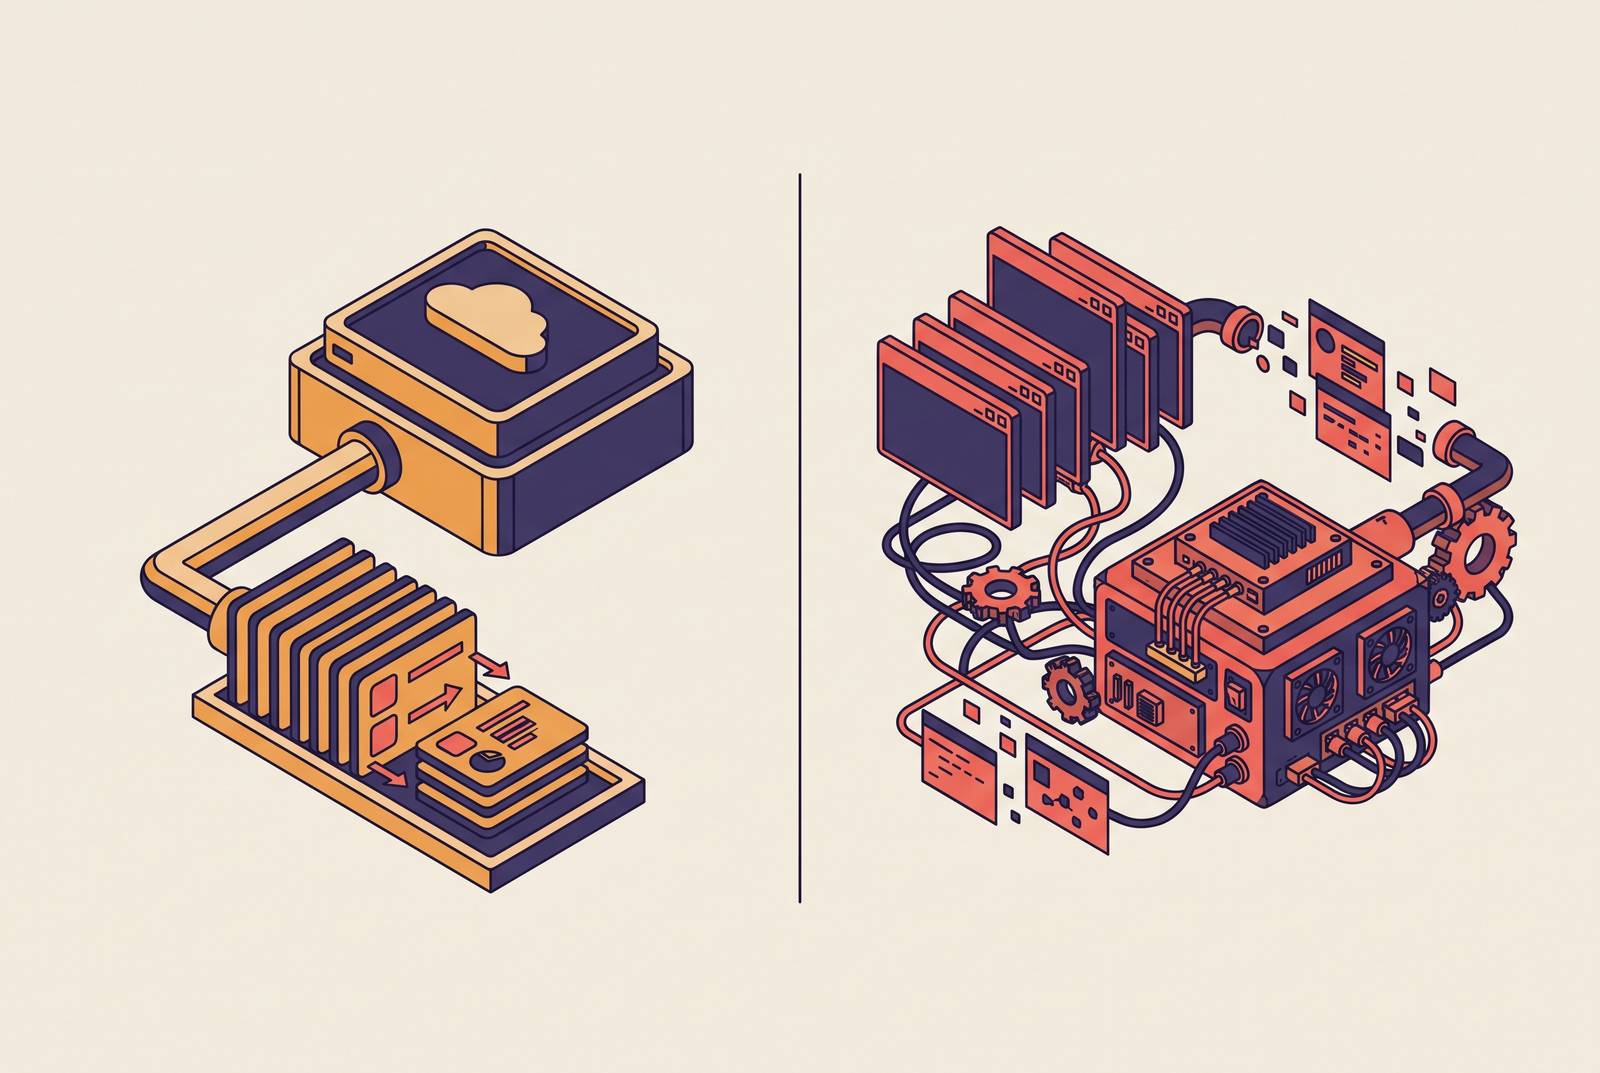
The two paths work differently from the ground up. With a managed API, a team sends a URL and gets back rendered content or structured data. The provider handles proxy rotation, CAPTCHA puzzles, fingerprinting, browser updates, and uptime. With a self-hosted setup, a team runs Playwright, Puppeteer, or Selenium on its own servers. That gives full control over a genuinely capable automation engine, but the browser was never the hard part. Proxies, fingerprinting, anti-bot defenses, and scaling all stay the team's job to solve and keep solving.
Plenty of early-stage teams default to self-hosting because the library itself is free to download. That framing misses where the actual cost lives. The cost appears later, in engineer-hours spent on proxy spend, debugging, and the maintenance work that never really ends. For a team with five or ten engineers, every hour spent keeping a scraper alive is an hour not spent on the product that scraper was supposed to support. It's whether this is what the team should be spending its limited engineering budget building.
The maintenance tax that compounds after setup
Setup time looks like the obvious place to compare these two paths, and on that measure the gap is real but not decisive. A managed scraping API can take about ten minutes to wire up. A self-hosted headless browser setup can take many hours before it's handling real traffic. That difference matters on day one. It is not what decides whether the choice pays off six months later.
What decides it is maintenance. A managed API rates low on this measure because the provider absorbs the work of keeping up with anti-bot defenses as they change. A self-hosted setup rates high, because browser updates, fingerprint rotation, and proxy management are standing obligations that keep arriving on their own schedule, whether or not anyone on the team has time for them that week.
Proxy rotation is the clearest example. Residential and datacenter proxies get burned and need replacing, and a rotation system solid enough to hold up in production runs forty to eighty engineering hours to build in the first place, with more hours required every month after as anti-bot systems keep evolving. Fingerprint drift is a quieter version of the same problem: headless Chromium ships with default settings that fingerprinting checks can spot easily, so keeping a browser identity that passes those checks means tracking new evasion techniques and patching them in, work with no connection to the product itself. CAPTCHA handling adds another layer. Without a solving service built into the pipeline, a blocked request just fails, or the team has to go integrate yet another vendor to cover the gap. Selector rot rounds it out: a site redesign breaks a brittle CSS selector, and someone has to stop what they're doing, diagnose it, rewrite the selector, and redeploy before the scraper works again.
None of these four problems runs on the same clock. Proxies burn out on one schedule, fingerprints go stale on another, selectors break whenever a target site happens to redesign. A team that self-hosts owns all four failure modes at once, so something is breaking somewhere most months. Anti-bot systems tend to evolve on a roughly monthly cadence, and scraping failures have an unfortunate habit of landing right around product launches, when a team can least afford an engineer pulled off feature work to go fix a selector. The self-hosted path looks cheap on a spreadsheet only when engineering time gets priced at zero. Price those hours at what they actually cost, and the picture changes.
Where self-hosting starts to make economic sense
None of this makes self-hosting the wrong choice everywhere. It makes self-hosting a choice that depends on conditions most early-stage teams don't yet have.
Volume is one condition. At high enough request volume, the per-request cost of a managed API adds up to more than the cost of running infrastructure directly, and the math shifts toward self-hosting. The second condition is DevOps capacity: self-hosting works when a team has data engineers dedicated to that infrastructure, people who aren't also the ones shipping product features that week. A managed API wins when speed to production is the constraint that matters most, which for most early-stage teams, it is.
Mature data teams often end up running both at once. Open-source tools cover static, simple targets where every request's cost matters and reliability needs are lower. Managed APIs cover JavaScript-heavy or heavily defended targets where getting the data reliably requires more than shaving cents off each request. That split is a reasonable way to run things once a team has grown into it.
The lock-in argument against managed APIs deserves a fair hearing too. Open-source tools give full control over browser identity, proxy choice, and where data lives. Managed APIs trade that control away in exchange for time saved and more stability. That trade only favors self-hosting when a team prices its own engineering time accurately going in. Teams that get that price wrong tend to find out after the first scraping incident takes down a launch, not before it.
Raising the bar on extraction quality for AI pipelines and RAG systems
AI pipelines expect more from extracted data than scraping ever used to demand. Traditional scraping handed back HTML, and whoever needed the data wrote a parser to deal with it downstream. AI pipelines need content already in a form a language model can reason over: Markdown, structured JSON, or fields validated against a schema. No amount of clever prompt writing fixes input that's missing fields or badly formed to begin with.
Language models carry a knowledge cutoff. They can't answer questions about last week's policy change or a product that launched yesterday unless something feeds them that information directly. A pipeline that fetches, cleans, and structures current web content is what lets a model answer accurately about anything after its training data ends. A RAG system depends even more directly on this: indexing stale or messy content degrades retrieval quality in ways that are hard to trace back to the cause and get worse the longer they go unfixed.
This changes what a self-hosted headless browser actually delivers against the job at hand. Playwright or Puppeteer hands back rendered HTML, full stop, nothing more. Turning that HTML into clean Markdown, checking extracted fields against a schema, and handling retries without silent failures are all extra layers a team has to build on top, or go find and integrate elsewhere. Each one is another thing to maintain alongside the proxy rotation and fingerprint patching already described. The convergence of harder-to-render pages, sharper bot detection, and the rising need for fresh data in AI pipelines has made this infrastructure question unavoidable for most teams building anything AI-native. It's why managed APIs built for LLM pipelines, Context among them, return rendered content as ready-to-use Markdown in one call rather than leaving that conversion work for someone else to do later. A managed API purpose-built for this collapses rendering, cleaning, and structuring into a single call: submit a URL, get back Markdown or schema-validated JSON ready to load straight into an index or a prompt.
Key criteria for a managed scraping API in AI-native use cases
Not every managed scraping API was built with AI pipelines in mind, and the gap between the ones that were and the ones that weren't becomes visible fast once a team starts using one in production. A handful of questions separate the two.
Output format comes first: does the API hand back Markdown that's actually ready for a language model to read, or does it still return raw HTML that someone has to convert before it's usable? Structured extraction matters just as much: can a developer pass in a JSON schema and get typed fields back directly, without writing a custom parser for every new site? Full-page JavaScript rendering needs to be a built-in part of the service, not a separate, pricier mode added later. Can the API work through an entire site on its own, or does it only handle one URL per request? Anti-bot handling should be built in rather than left for the team to solve with a separate proxy layer. Integration surface matters for anything agent-driven: does the API expose an MCP server or another interface agents can call directly, or only a standard REST endpoint? And for products that need company or brand context, check whether that kind of enrichment data sits behind the same API key or requires yet another vendor relationship.
These failure modes, proxy rotation, fingerprint evasion, CAPTCHA handling, and selector upkeep, might look like separate problems from a distance, but they're coupled. They tend to break in the same stretch of weeks, often right as anti-bot systems update and right when a product launch needs everything working. Folding all of that into one managed API, instead of stitching together a proxy service, a fingerprinting library, and a CAPTCHA solver separately, removes the ongoing triage that otherwise eats into a small team's engineering time.
Context.dev: a single API covering scraping, crawling, structured extraction, and brand data
Context.dev was built around the AI-pipeline use case specifically, and it replaces a stack that would otherwise need a scraper, a crawler, a Markdown converter, a structured-extraction service, and a brand-data vendor, all stitched together separately.
A single API call can turn any URL into Markdown ready for a language model, crawl an entire site rather than one page at a time, extract structured data against a schema a developer defines, and pull in brand intelligence, logos, colors, fonts, and firmographic details, all under one API key. That combination maps directly onto the criteria laid out above: Markdown comes back natively rather than as raw HTML needing conversion, and schema-validated JSON goes straight into a RAG index or an agent's context window without an extra processing step in between.
The underlying argument for consolidating down to one API is the same one that runs through the rest of this piece. Teams that currently run a scraper, a separate Markdown converter, a structured-extraction tool, and a brand-enrichment vendor are maintaining four relationships instead of one, each with its own billing, its own integration, and its own way of breaking. Context.dev brings that down to one dependency. Getting from nothing to a working API call takes minutes rather than days, since the rendering, anti-bot, and formatting work is already done on the provider's side. Mintlify, SiteGPT, and Sourcely all run Context.dev as the data infrastructure layer behind their own products and agents, and the company is backed by Y Combinator.
Other managed APIs worth considering, matched to specific needs
Beyond Context.dev, a handful of other managed APIs cover specific needs well, and which one makes sense depends on what constraint matters most to a given team: cost per request, proxy scale at enterprise volume, or fit with an existing codebase.
ScraperAPI makes sense when pages are relatively simple and cost per request is the main thing a team is optimizing for. JavaScript rendering is available, though it runs at a higher credit cost, which makes it a reasonable fit for high-volume, low-complexity scraping where output format flexibility matters less than keeping the per-request price down.
Bright Data and Oxylabs are at the enterprise end of the market, with large proxy networks, formal compliance programs, and dedicated account management built for large-scale unblocking and regulated industries. Both carry more setup complexity and custom pricing than an early-stage team typically needs, which makes them a better match for data teams that are already established than for a product still finding its footing.
Zyte fits well for teams already running production pipelines on Scrapy, since it sits close to that ecosystem. It offers automatic extraction, though teams building for AI use cases should check how well its schema coverage matches what their pipeline actually needs before committing to it.
Choosing among these options comes down to the same resource question that opened this piece: not whether a team is technically capable of running a headless browser and managing its own infrastructure, but whether proxy management, fingerprint patching, and CAPTCHA integration are the best use of engineering hours that could otherwise go toward the product itself. For most early-stage teams, handing that infrastructure to a managed API and keeping the engineering budget pointed at features is the more durable bet.