Giving OpenAI Agents SDK Tools Access to Live Web Content
OpenAI Agents SDK now connects to live web data through fetch, extract, and crawl tools.
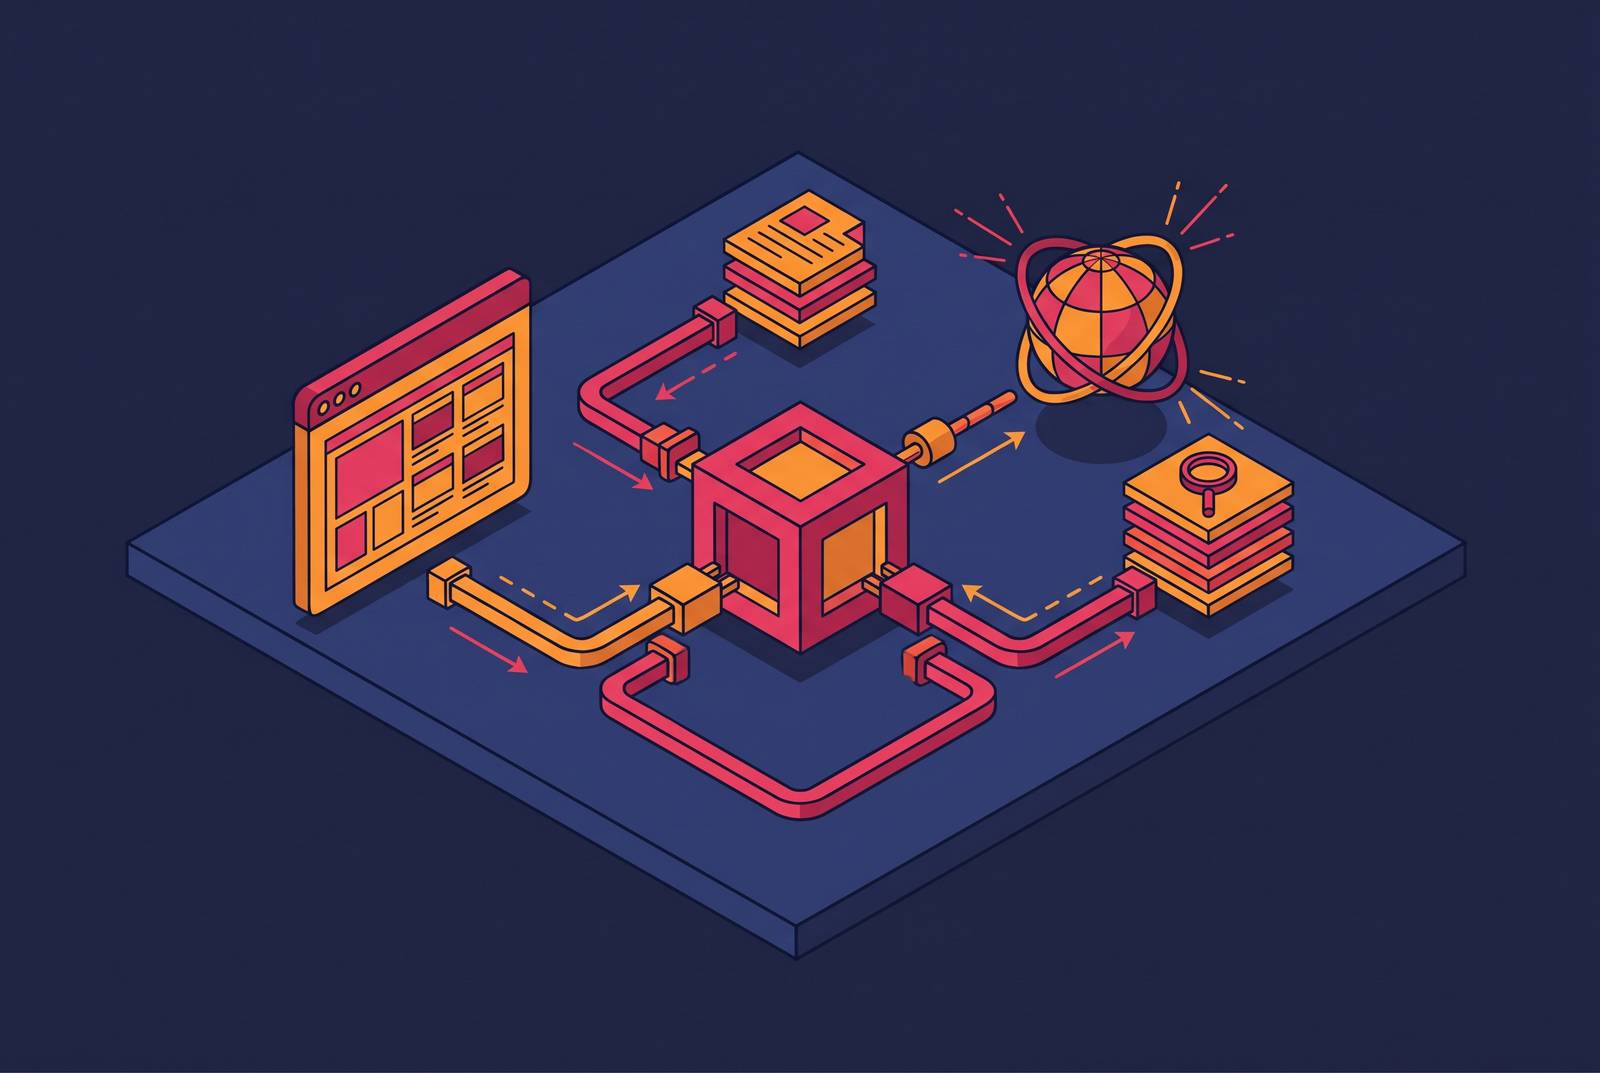
A web scraping pipeline for OpenAI Agents SDK tools needs separate stages for discovery, fetching or crawling, extraction, storage, and freshness. Built-in web search handles the discovery stage of the pipeline. FunctionTool wrappers and remote MCP tools supply full-page text, typed fields, and site-wide data without changing the agent layer.
Why the Agents SDK's built-in web search is not enough for production agents
OpenAI’s Agents SDK supplies the core pieces for building agents, including Agent, tools, handoffs, guardrails, and sessions. Its hosted WebSearchTool gives those agents a way to search the web. That is useful, but it has a boundary. Surface-level retrieval does not give a developer the same control as fetching a complete page, extracting fields against a schema, or crawling a site.
The SDK’s tools page lists WebSearchTool settings including filters, user_location, search_context_size, external_web_access, search_content_types, and image_settings. Those settings shape search behavior, but none provides full crawled page bodies or schema-defined extraction. A task that depends on a whole documentation article therefore needs a different data operation from a task that merely needs to find that article.
Freshness adds a separate constraint to that boundary. Models have knowledge cutoffs, while pages can change after the model’s training. Search can point to a current source, but a snippet naming that source is not the same as fetching and parsing its current contents.
How the Agents SDK tool abstraction works, and why it is the right seam for external data
A Python function decorated with @function_tool becomes a callable tool that the agent can discover and invoke. The function can wrap a web fetch, a parser, or an extraction API. Its signature defines what the agent passes in. Its return value is the data the agent gets back, so FunctionTool connects the agent directly to external web services.
The SDK separates that mechanism from other kinds of tools. Hosted tools, including WebSearchTool, FileSearchTool, and CodeInterpreterTool, execute on OpenAI servers, while agents-as-tools expose another agent as a callable. ComputerTool and ApplyPatchTool run in the developer’s environment, while ShellTool can run locally or in a hosted container. The experimental Codex tool serves workspace-scoped tasks. These distinctions determine where an operation executes.
HostedMCPTool offers another route for external web data. It exposes a remote MCP server’s tools, with optional allowlisting, without requiring custom dispatch code. For larger tool collections, ToolSearchTool defers loading until runtime. The SDK’s guidance recommends namespaces or hosted MCP servers over deferring many functions one by one because they give the model a clearer view of the tools it can search.
What agents actually need from web data, and why those needs exceed a search snippet
The first decision is whether the agent needs text, fields, or a corpus. A known URL and a reading task call for full-page content retrieval. Examples include a competitor’s pricing page, a documentation article, or a regulatory filing. A snippet cannot stand in for the complete rendered text. If the needed content is rendered by JavaScript, a plain HTTP GET is not enough, and the retrieval layer needs a headless browser or rendering service.
If downstream logic needs values rather than prose, structured extraction is the better fit. Price monitoring needs a price. A developer-defined JSON schema makes the required fields explicit and gives the extraction call a predictable output contract.
If the question spans a site, the unit of retrieval changes again. All pages under a docs subdomain or all products in a category require a crawler that traverses links, respects depth limits, and handles pagination. Repeated single-page calls are not a substitute for that coordination. The choice follows the task’s required output, rather than a general wish to give the agent “web access.”
Three integration patterns for getting live web content into an Agents SDK tool
The simplest pattern is a FunctionTool wrapping a URL-to-Markdown API. Its decorated function accepts a URL and, where supported, a CSS selector or content hint. It calls the external service, handles the response, and returns a Markdown string. The agent chooses when to invoke it. This is the lowest-friction starting point when the missing capability is reading a known page.
The second pattern keeps the function wrapper but changes the contract. The function accepts a URL plus a JSON schema, or uses a fixed schema for a known source, then returns a typed dict from an extraction endpoint. This works for price monitoring, lead enrichment, and content metadata. The structure arrives already parsed, rather than requiring the agent to convert a prose dump into fields.
The third pattern connects HostedMCPTool to a web-data MCP server. One endpoint can offer fetch, extract, crawl, and brand-data operations without the need to write dispatch code for each one. It offers a broader tool surface out of the box. The trade-off is dependence on a provider that publishes an MCP server and trust in its remote execution environment. A crawl can run with or without MCP, which can bundle the wider set of operations the crawl needs.
Fetching a single page cleanly: turning a URL into LLM-ready Markdown
A single-page function tool has a narrow job. It takes a URL, calls the content API, and returns clean Markdown. For JavaScript-rendered content, the chosen service must render the page.
HTTP errors from the target page, including 4xx and 5xx responses, should return a clear error string so the agent can decide whether to retry or move on. Paywalls and login gates need explicit signals. If the tool returns empty or partial text without saying that access was restricted, the agent cannot tell whether content is missing or access is blocked.
Long pages create a different problem because successful retrieval can still return more text than the task needs. A max-tokens parameter or selector can scope the fetch to the relevant section. The agent’s instructions should also distinguish this tool from WebSearchTool. Search finds a source, while fetch reads its full content once the URL is known.
Extracting structured fields from a page using a developer-defined schema
Structured extraction moves parsing out of the agent’s reasoning loop and into the data layer. Asking the model to turn a prose dump into fields is less reliable and more token-expensive than receiving those fields from a schema-aware API. The schema is the contract between the tool and downstream logic. It names both the values required and their expected types.
A product-page schema can define name, currency, availability, and sku as strings, with price as a float. A job-listing schema can request title, company, location, salary_range, and posted_date as strings. A news-article schema can request headline, author, published_at, and body_summary.
The tool returns a Python dict. Downstream logic can pass that dict onward, write it to a store, or compare a field against a previous value without another prose-parsing step. This is also a useful boundary for delegation. A dedicated extraction sub-agent can expose the same operation to an orchestrator while keeping the extraction logic isolated and testable.
Crawling an entire site and feeding the corpus to an agent or RAG pipeline
The input for a site-wide question comes from linked pages in a documentation site, product catalog, or news section. The crawler handles traversal, depth limits, and pagination, then returns a coherent corpus.
For larger sites, crawled Markdown documents become input to a retrieval-augmented generation, or RAG, pipeline. The documents are chunked, embedded, and written to a vector store, such as the stores used by OpenAI’s FileSearchTool. The agent then retrieves relevant chunks through FileSearchTool. Storage turns the crawl into a reusable source.
That reuse introduces a freshness obligation for the index. A crawl that runs on a schedule or at query time keeps the indexed content up to date without anyone having to re-ingest it by hand. WebSearchTool can find domains that fit the task before a crawl gathers their content in depth. Rendering and crawl support help retrieve content, but access can still be blocked.
Wiring web tools into multi-agent workflows: orchestrators, sub-agents, and handoffs
When every agent has its own fetching and parsing tools, they repeat calls and handle the data in different ways. A dedicated web-data sub-agent provides a cleaner boundary. It owns a narrow set of fetch, extract, and crawl tools, while the orchestrator holds the business logic. Other agents delegate retrieval to that sub-agent.
The SDK offers two distinct delegation mechanisms. With agents-as-tools, the orchestrator calls the specialist, receives a return value, and continues its own reasoning. This suits work whose result belongs inline. A handoff instead transfers control to the specialist for a longer, multi-step retrieval task. The architectural distinction is whether the orchestrator needs a tool result or needs another agent to take over the work.
Box’s use of the Agents SDK illustrates the enterprise motivation for this separation. Its agents combine web search with proprietary internal data, routing queries to the right source while respecting internal security policies. For workflows with many tools, ToolSearchTool also lets the orchestrator defer loading the web-data namespace until a query needs live content. Turns that do not need the web avoid that tool-schema overhead.
Security constraints that apply specifically when agents fetch live web content
Fetched pages can contain instructions aimed at the agent. So bringing arbitrary web content into the reasoning loop gives prompt-injection a way in. Live retrieval expands the source boundary beyond a static indexed corpus. The security design must account for that boundary before the agent is allowed to fetch freely.
If an agent can read API keys from its environment, an injected instruction may try to make it disclose them. Each tool needs keys with minimal permissions and a sandboxed execution environment. OpenAI names Blaxel, Cloudflare, Daytona, E2B, Modal, Runloop, and Vercel among its supported sandbox providers. That execution boundary limits what a compromised tool call can reach.
URL allowlisting belongs inside the fetch function so injected instructions cannot simply direct it to an arbitrary destination. The SDK’s Guardrail mechanisms belong in the broader safety design, but they are not a replacement for URL restrictions, key scoping, or sandbox isolation. Those controls constrain access even when the fetched text tries to redirect the agent.
Keeping agent knowledge current: change detection and freshness TTL as pipeline events
On-demand fetching updates an answer, but it does not maintain a knowledge base. A documentation index, price table, or regulatory reference needs a clear policy for how fresh its content must be. Values that change quickly, such as prices, scores, and live data, need to be fetched at query time without a cache. Fast-changing news, CVEs, and competitor announcements call for freshness measured in hours, while docs, product pages, and regulatory references can use days to weeks.
Static reference content can be crawled once and invalidated when a change is detected. A change alert can fire a webhook that triggers a re-crawl, making freshness an automated pipeline event. Semantic-diff monitoring narrows those events to meaningful changes, such as new products or updated pricing tiers. Timestamps, rotating testimonials, and layout shifts need not trigger the same work. The developer defines which changes count.
In this architecture, the orchestrator queries the vector store first for known stable content and falls back to live retrieval when needed. Scheduled crawls replenish stored Markdown, while sensitive tool calls run within a sandbox boundary. The system can grow incrementally from one URL-to-Markdown FunctionTool to structured extraction, site-wide crawling, and scheduled freshness. The agent layer can stay as it is while the need for data grows.