Company Category and Industry Classification From Website Content
Extract industry classifications from website text using the right taxonomy and clean content.
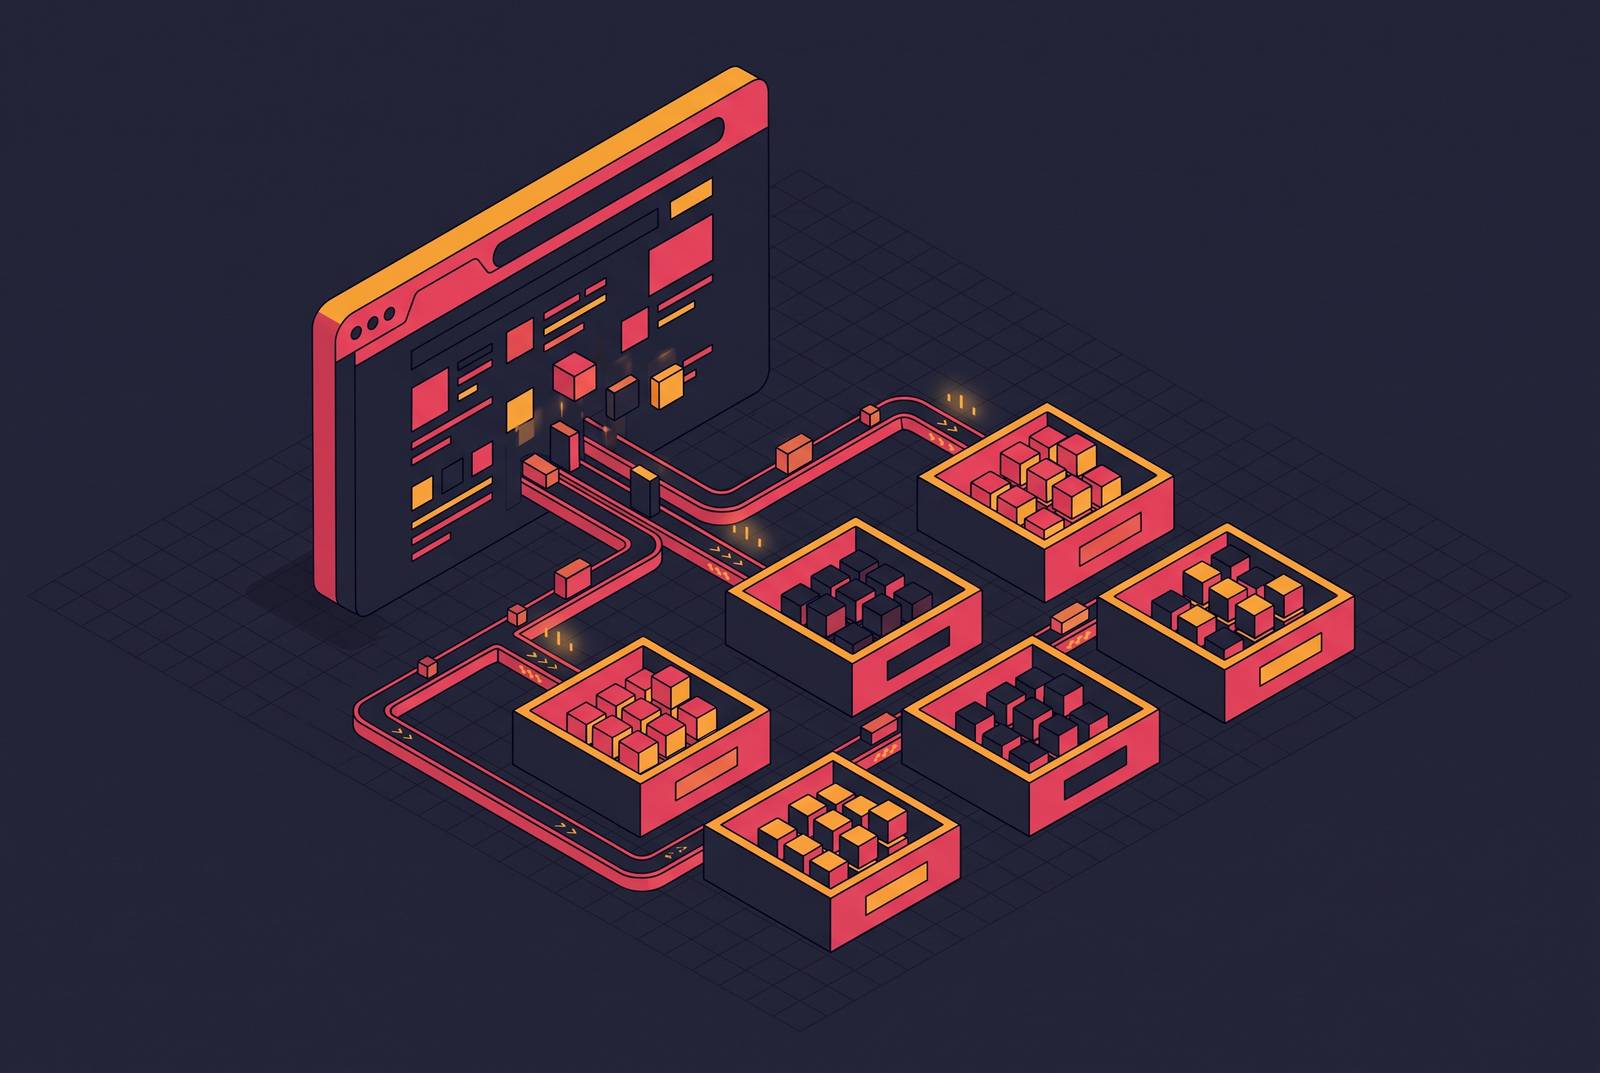
Company category and industry classification from website content is a problem of turning live business descriptions into structured data. A company’s website is the most authoritative and current signal of what it does, but raw pages are not usable industry labels. Reliable classification depends on choosing the right taxonomy, extracting clear evidence, and refreshing the result as the business changes.
Why company websites are the most current signal for industry classification
A company controls its website and uses it to describe its current positioning, products, and customers. That makes the site a more timely account of its business than a static registry or purchased list. When the company changes what it sells, its published pages can reflect that change before an external record catches up.
OMB reviews NAICS every five years, while SIC has not been updated since 1987 and is no longer actively maintained. A business that has pivoted may keep its old code until a re-filing or census update. Purchased B2B contact and firmographic databases also decay, so an industry tag attached to a domain may describe a past business.
Website content can get around that delay, though the company's claims may not match what it does to earn money. It gives the classifier direct access to the company’s latest account of its product portfolio. Jagrič and Herman (2024) frame their BERT-based classifier as harnessing real-time web data to use the latest information affecting that portfolio.
What classification schemes a pipeline needs to know about before touching a website
“Classify a company” is not a complete specification. The pipeline first needs a taxonomy to work with, because each scheme answers a different question. NAICS serves government reporting and statistical filings, with the primary code attached to the line of business generating the most revenue. A company with several business lines can legitimately hold several codes. Asking a classifier for a single label therefore introduces a constraint that the business itself may not satisfy.
IAB taxonomy serves advertising and content monetization, so it is a different classification target. NAICS and IAB do not map cleanly to each other. A pipeline that feeds government reporting needs to extract different information from one that feeds an advertising or GTM system. Broader schemes, such as the 13-category scheme in Jagrič and Herman (2024), give up some detail for signals that change less and help with peer-group analysis. Choosing the scheme first determines which pages matter, what the output must contain, and how the result can be validated.
Which pages on a company's website carry usable classification signal
The homepage is the minimum fetch because it usually states the company’s primary positioning. It often contains the clearest short description of what the business does, but that description may be written to attract attention and leave the industry boundary unresolved. The About or About Us page is usually the next most useful source. It can explain the business model, history, and mission in terms the homepage leaves out. These pages show what the company claims to be, without a crawl of everything it publishes.
Product and Services pages then test that identity against what the company actually delivers. For a technology company, they can distinguish software products from professional services or managed services. That distinction matters when the homepage blends all three into broad marketing language. Job postings add a different kind of evidence because the roles a company is hiring for reflect its operational structure and technology stack. They can be more candid about the work being done than the copy written to sell it.
Footer text, legal disclaimers, and navigation labels may contain identifiers such as “licensed insurance broker” or “FDA-registered” that confirm or override an initial inference. Their value is a reason to select content carefully. More pages can add text that has no bearing on the choice and raise token costs. The goal is a compact body of evidence that explains what the company delivers and resolves the distinctions the chosen taxonomy requires.
How to turn fetched page content into a clean classification input
Raw HTML mixes the business description with material that does little to help classify it. Scripts, tracking pixels, inline stylesheets, repeated navigation, and boilerplate compete with the text the model needs. Turning HTML into Markdown or clean prose strips away clutter from how the page is displayed and keeps what the text says. This is the bridge between fetching a page and having a usable classification input.
The pruning step needs to distinguish repetition from evidence. A navigation footer may be noise, while a regulated-industry identifier inside a footer may be important. Stripping both indiscriminately would remove the very detail that could correct a misleading homepage. The aim is therefore to discard structural clutter while preserving business descriptions and relevant qualifiers. Clean input is not simply shorter input, but input in which the remaining words do more useful work.
At scale, that distinction affects both cost and accuracy. Clean Markdown uses fewer tokens than raw HTML and gives the classifier less text it has to ignore. However, evidence for a classification model should not be mistaken for evidence for a complete extraction pipeline. Jagrič and Herman (2024) used business descriptions taken from websites and held in an existing labeled database to fine-tune BERT. They did not build a two-stage extraction-then-classification pipeline, so their results do not settle how well a particular fetching or cleaning method works.
How to prompt or model against clean web content to produce a structured classification
Once the input is clean, the choice of model depends on how finely the taxonomy divides businesses and how much labeled training data exists. A coarse, stable scheme with rich training data is a good fit for a fine-tuned transformer. Jagrič and Herman (2024) fine-tuned BERT to classify business descriptions into 13 industry categories, achieving overall accuracy of 88.23% and an F1 score of 0.88. That is a strong result for the scheme they used. It is not evidence that the same approach will handle a much finer taxonomy equally well.
Performance also varied across categories. Healthcare, consumer staples, and financials were at the high end of the range, while consumer discretionary and information technology were at the low end. In the weaker categories, the marketing language companies use does less to set them apart. This matters because a model can only learn distinctions that the descriptions support. Fine-tuning works well when the labels are stable and the examples are informative, but greater detail exposes limits in both the data and the scheme.
For granular taxonomies with sparse examples, an LLM paired with retrieval-augmented generation, or RAG, is the better fit. In the WZ 2008 German classification example, a knowledge guideline helps match descriptions to thousands of industry codes. That guideline supplies each code’s definition, examples of when it applies, and exceptions where it should not be used. Retrieval gives the model those boundaries when it makes the classification. The model is not expected to have memorized the full codebook during training.
The prompt must turn that evidence into a result another system can consume. It should distinguish what the company sells from how the company describes itself, then request a JSON object containing a primary code, a confidence indicator, and a brief evidence-based rationale. An explicit JSON schema is more reliable than asking for free text and trying to parse it afterward. The rationale makes the decision auditable, while the defined fields allow downstream validation. Klazify’s categorization API illustrates the API-first form of this pattern by classifying a URL across 621 IAB categories.
Where classification from website content breaks down and how to handle the failures
A managed marketing services firm may call itself “technology-enabled” without selling a technology product as its main business. A classifier that follows the prominent terminology can assign the wrong code even when it reads the page correctly. For NAICS, the decisive activity is the one generating the most income. The prompt should separate what the company sells from how it describes itself, while recognizing that this only partially reduces the error.
Diversified businesses create a different problem because the homepage may describe a corporate umbrella and leave its operating activities unclear. The pipeline should fetch subsidiary or division pages when the domain is known to represent a holding structure. Even then, forcing a single primary code can hide the company's real ties to several industries. Jagrič and Herman (2024) identify diversification and vendor-specific inconsistencies as structural challenges, noting that revenue-based rules may produce biased classifications. A fuzzy or multi-label treatment can be more honest where the downstream use permits it.
Published claims from pivot-stage startups can also be misleading when taken at face value. Their homepages may describe an intended future identity rather than the activity currently generating revenue. The site can be accurate as marketing and still misleading as classification evidence. Low-information homepages create a related problem by saying too little to support a confident choice at all. Because some domains lack enough evidence to classify, the pipeline needs a fallback and a confidence threshold that sends results for human review when they fall below it.
Freshness also has to survive ingestion. A RAG-based classifier that indexes website content is only as current as its last crawl, regardless of how often the live site changes. If the stored content is stale, the live-web advantage has already been lost before the model starts. Ingestion timestamps and staleness thresholds therefore belong in the pipeline as required controls. These controls address a different failure from model accuracy, because even a correct reading of old evidence can produce an outdated label.
Treating classification as an ongoing pipeline primitive rather than a one-time lookup
A successful classification records an assessment as of a date and can change over the life of a domain. Companies change the products they sell, their business focus, and how they present themselves, so a label from a single crawl will grow stale over time. The appropriate trigger for re-classification is a material website change. A rewritten About page, a new products section, or the disappearance of a service offering can all justify another pass. This ties the work to changes in the evidence instead of assuming that elapsed time alone signals a new industry.
Historical snapshots make those changes visible. Comparing key pages over time can expose a shift that the company has not announced publicly, such as a pricing page quietly dropping a product line. An agentic pipeline can keep running change detection and send domains for re-classification when the changes pass a materiality threshold. In that design, the classifier is a tool the agent invokes when needed.
For GTM and sales intelligence, firmographic data in a CRM or enrichment layer will drift away from what companies actually do if it has no live-crawl refresh cycle. A production pipeline therefore needs four components, which are a crawl layer, a change-detection layer, a classification layer, and a staleness policy. None is solved by a one-time setup. Website classification earns its advantage only when the pipeline keeps the evidence clean, the output structured, and the assessment current.