Extracting Social Profiles and Contact Signals From Company Websites
Structured data extraction turns scattered website signals into reliable inputs for AI pipelines.
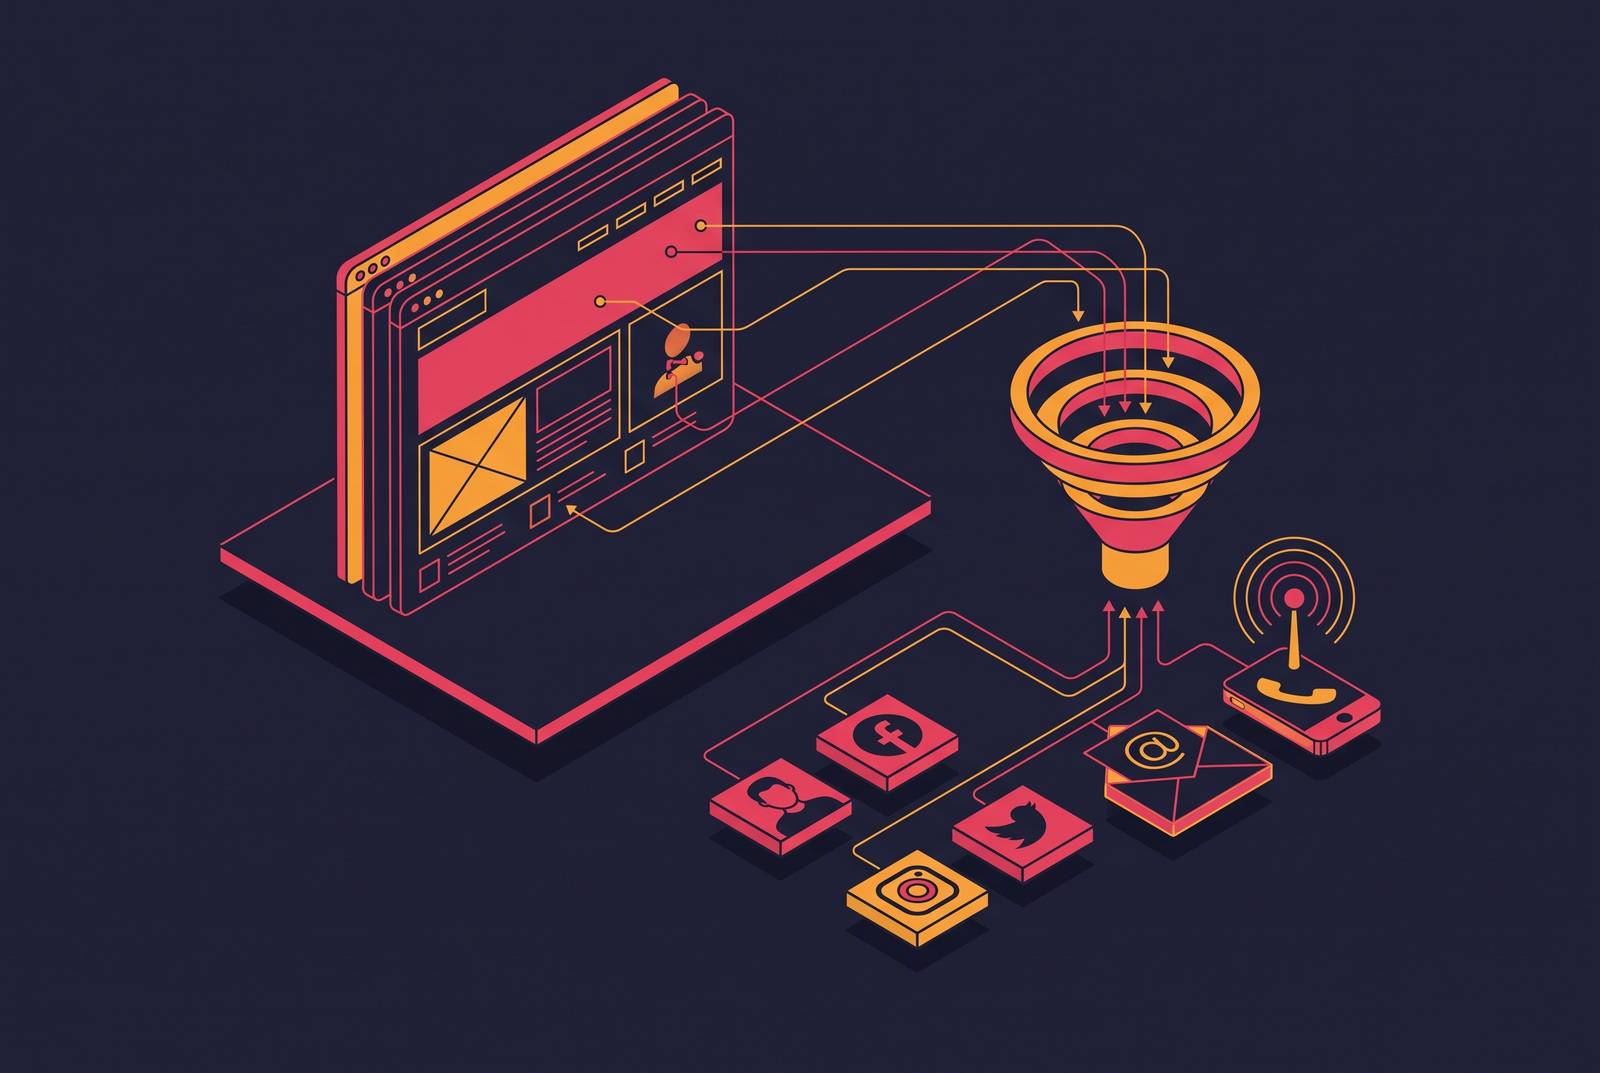
Extracting social profiles and contact signals from company websites is a structured data problem. The clearest approach is to define each signal in a schema, target the pages that hold it, and use an API to return typed data. That turns scattered links, addresses, and team details into inputs that AI pipelines can use reliably.
Why contact and social data extraction has become a structured data problem
Contact data now feeds AI pipelines, GTM agents, and enrichment workflows, but its retrieval often still depends on page-specific scraping rules. Those rules tie the meaning of a value to its position in a layout. When a site redesigns, a selector-based scraper can break silently even though the information remains on the page. When this happens across many company websites, the infrastructure needs work that goes beyond a fix now and then.
The underlying mismatch is between how websites present information and how software needs to consume it. A LinkedIn URL inside a footer icon, a Twitter handle in a bio, and an email inside a contact modal are all social or contact references. Their placement does not define their identity. A pipeline needs that identity expressed precisely, with a known type and a way to validate it, rather than a string whose meaning depends on where it was found.
The five signal types that matter and how they differ as extraction targets
Social profile links are often the cleanest targets. LinkedIn company pages, Twitter/X handles, and GitHub org pages usually appear in footers, navigation, or About sections. A link pointing to a known platform domain provides stronger evidence than a “follow us” label without a resolvable link target. Predictable URL patterns help, but vanity URLs and JavaScript-rendered components can complicate discovery.
Email addresses need a different strategy because their visible form varies. Contact pages, team bios, and press pages may have addresses in plain text or as email link targets. Other sites replace punctuation with words, render addresses as images, or offer only a contact form. An address inferred from a naming pattern is therefore not equivalent to one extracted from the page. That distinction matters even when the inferred address looks plausible.
Phone numbers bring formatting and ownership problems. They appear in footers, contact pages, and structured data markup, but their formats can differ a lot from country to country. A main company number is also a different signal from an individual’s direct dial. Finding the latter may require opening a separate profile page.
Named team members require more interpretation than any of these targets. A bio may mention both a current job and a past role, while prose about leading engineering may support an inferred title without stating one. Team pages can also paginate or lazy-load, so one page fetch may not produce a complete roster. Firmographic and brand signals, including HQ address, founded year, company size, and logo URL, are usually less inference-heavy. Their presence in structured markup, footers, and About pages often makes them cleaner extraction targets.
Designing schemas that capture what you actually need
A JSON schema defines success before the extraction request runs. It specifies which values belong in the result and what form each value must take. That makes results comparable and validatable instead of leaving downstream code to interpret freeform text. The schema is a contract.
For company contact data, a short sketch of the fields could read {linkedin_company_url = URL string, twitter_url = URL string, github_org_url = URL string}. Contact fields could include {email_general = email string, email_press = email string, phone_main = E.164 string, hq_address = string}. A URL field should reject a handle such as @company, because a handle is not a URL. The field definitions should also distinguish a company LinkedIn page from a personal profile and a press address from a general inquiry address.
Repeated values need arrays. Each email address and team member should have a separate record so they do not end up together in an unparsed string. A source_location field preserves where a value appeared, while a confidence field can support downstream validation. These fields make doubtful results easier to check and show where one extraction is less certain than another.
Individual profiles need their own schema. A useful sketch is {full_name = string, inferred_title = string, stated_title = nullable string, linkedin_profile_url = nullable URL string, email = nullable email string, bio_excerpt = truncated string}. Keeping inferred_title and stated_title apart shows which title was inferred and which was stated on the page. With nullable fields, a profile can still be useful when it has no email or social link. This separation also makes it clear where page-level discovery ends and deeper profile enrichment begins.
Which pages to target and in what order
Start with the homepage because it offers a fast, low-cost pass over company-level signals. Social footer links, a general contact address or link, and a header phone number often appear there. One request can find most social profile signals without having to go through the whole site. The next stop is the contact page, where email addresses and phone numbers tend to be concentrated. It also helps distinguish general inquiries from press or partnership contacts.
Move to the team page when the goal includes named people. Paths such as /team, /people, /leadership, and /about/team are primary targets for this work. Because those sections may paginate or require JavaScript rendering, a scoped crawl is often more appropriate than a single fetch. Press or News pages then provide a secondary source for executive names, titles, and press contacts.
About pages are useful for firmographic details and social links that may overlap with the homepage. That overlap is evidence to normalize and deduplicate into one record for the same LinkedIn URL. The depth of the crawl should follow the goal. Homepage and contact-page fetches are sufficient for company-level social and general contact signals, while a complete team roster calls for a shallow crawl scoped to the team section. Targeting the right pages reduces noise, token cost, and later disambiguation.
How a well-designed API handles this extraction reliably across arbitrary layouts
A well-designed extraction API separates page retrieval from signal interpretation. It converts page content into clean, boilerplate-stripped Markdown or structured JSON before applying extraction logic. That separates what a page says from where its content sits in the DOM. The caller supplies a JSON schema, and the API returns the requested fields validated against their specified types.
JavaScript rendering, lazy-loaded content, and pagination should not force the caller to build a different extraction path for each website. A site-scoped crawl should accept a URL prefix such as /team and retrieve and extract across matching pages. That makes a paginated team section one scoped API request rather than a pagination and URL-discovery loop maintained by the developer. The response can then enter the pipeline without a separate parsing layer.
This is a different trade-off from database-backed enrichment. Platforms such as ZoomInfo, Apollo, and Cognism offer pre-verified contact records without per-page latency, making them fast for high-volume lookups against known companies. Live extraction matters when a newly hired executive, rebranded social handle, or changed contact address has not reached a static database. Freshness and bulk speed serve different needs, so the approaches can complement each other. The practical case for an extraction API is strongest when a team needs current page data and a working integration in minutes.
Operationalizing extracted signals in an AI pipeline
Typed data becomes useful when it has a destination and a refresh trigger. To ground generated responses in retrieved data, index extracted contact and social records in a retrieval store keyed by company domain. An agent answering a company question or preparing personalized outreach can then retrieve the freshest extracted record. A freshness TTL determines when the indexed record needs another crawl.
Agentic enrichment builds a fuller record by making one extraction call after another. The workflow takes social links from the homepage, emails from the contact page, and named members from the team section. Each step uses the same schema contract for the fields it fills, so the company profile is type-consistent when the results are joined. Outreach writers, qualification scorers, and CRM updaters can consume that object as structured input.
When a team page adds someone, a social handle is new, or a contact email changes, that change can trigger another extraction job without a full periodic crawl of every record. Quality checks still belong at extraction time, including email-format and domain validation. Inferred titles should remain flagged so downstream agents treat them as lower-confidence inputs. Across runs, deduplication should use the canonical company domain rather than the page URL, accounting for www and non-www forms and redirect chains.
What compliance requires when extracting personal contact data
Extracting named individuals’ emails, phone numbers, or professional profiles constitutes personal data processing under GDPR and similar frameworks. The fact that a person’s details appeared on a website is not, by itself, a lawful basis for processing them. Company-level extraction and individual contact collection therefore need different risk assessments.
Authentication is a separate boundary. hiQ v. LinkedIn dealt with access to truly public pages under the CFAA and gave no blanket permission for every use of scraped data. Meta v. Bright Data backed that distinction for public, logged-off access, though the case was decided mainly on contract grounds. Neither is a reason to bypass login gates. Access rules and personal-data rules apply to different parts of the same pipeline.
When commercial extraction relies on legitimate interest, the developer needs to write down a three-part test of purpose, necessity, and balancing. Official company social pages, general contact or press addresses, main phone numbers, and HQ addresses expose less personal data than individual records do. Personal emails, direct dials, and individual LinkedIn profiles collected into an outbound database require a much stronger compliance posture.
In December 2024, a French regulator fined a contact data company and ordered it to stop collecting and delete data from people who had restricted the visibility of their contact details. The deletion order concerned only that unlawfully collected data. For pipelines that need individual contact data at scale, a GDPR-compliant provider with a documented lawful basis is the safer architecture than building both scraping and compliance infrastructure. A reliable API handles extraction, but it does not supply the developer’s lawful basis.
From ad hoc scraping to a repeatable extraction architecture
Keep a library of schemas for company contact data, team members, and brand intelligence, and track their versions. Those schemas should change when the required signals change and remain stable when a website rearranges its pages. A page-targeting configuration then maps company domains to the appropriate scope, from homepage and contact-page fetches to team-section crawls for accounts where people data matters.
Freshness policy belongs in the same architecture. Social links and brand data can have longer TTLs, while contact emails and team rosters need shorter ones or change-triggered re-extraction. Downstream consumers should depend on the typed output contract. Treating the API as an internal data service gives those consumers a stable interface and keeps schema drift from breaking them. The choices made for compliance set the limits on which signals that service should collect.
The practical payoff is consolidation. Replacing a bespoke social-link scraper, a separate email finder, and manual team-page review with a schema-driven extraction API reduces the maintenance surface and gives the results consistent types. New signal requirements can become schema changes. One target company’s homepage and a simple contact schema provide the basis for a first working API call from which the system can grow.