Auto-Populating Company Profiles in B2B SaaS From Website Data
Extract company data from websites into CRM fields using JSON schemas.
Auto-populating company profiles in B2B SaaS is a structured data extraction problem. A pipeline that follows a JSON schema can use a prospect’s domain to extract content from its public website into CRM fields. The fix is to define the data contract first, then build fetching, extraction, validation, and refresh around it, rather than stitching together manual research and fragile parsers.
Why company profile data is broken before it ever reaches the CRM
A CRM cannot repair a company profile that was wrong when it arrived. Manual SDR research, static enrichment databases, and one-off scraping scripts all feed that problem, but for different reasons. Manual research is slow and inconsistent, and it does not scale past a few hundred records per rep per week. A purchased record shows the company as it was when the provider last crawled it, which may differ from how it is today. A bespoke scraper depends on page structure that the prospect has no obligation to preserve.
An outdated headquarters location can send a prospect down the wrong routing path, while a wrong employee count can distort qualification. A layout change can also leave a parser returning the wrong content without raising an error. Those stale or missing values weaken personalization, waste SDR time, and corrupt the ideal customer profile scoring models that depend on them. The friction starts at collection, so another cleanup step inside the CRM is not a structural fix.
What a schema-driven extraction pipeline actually replaces
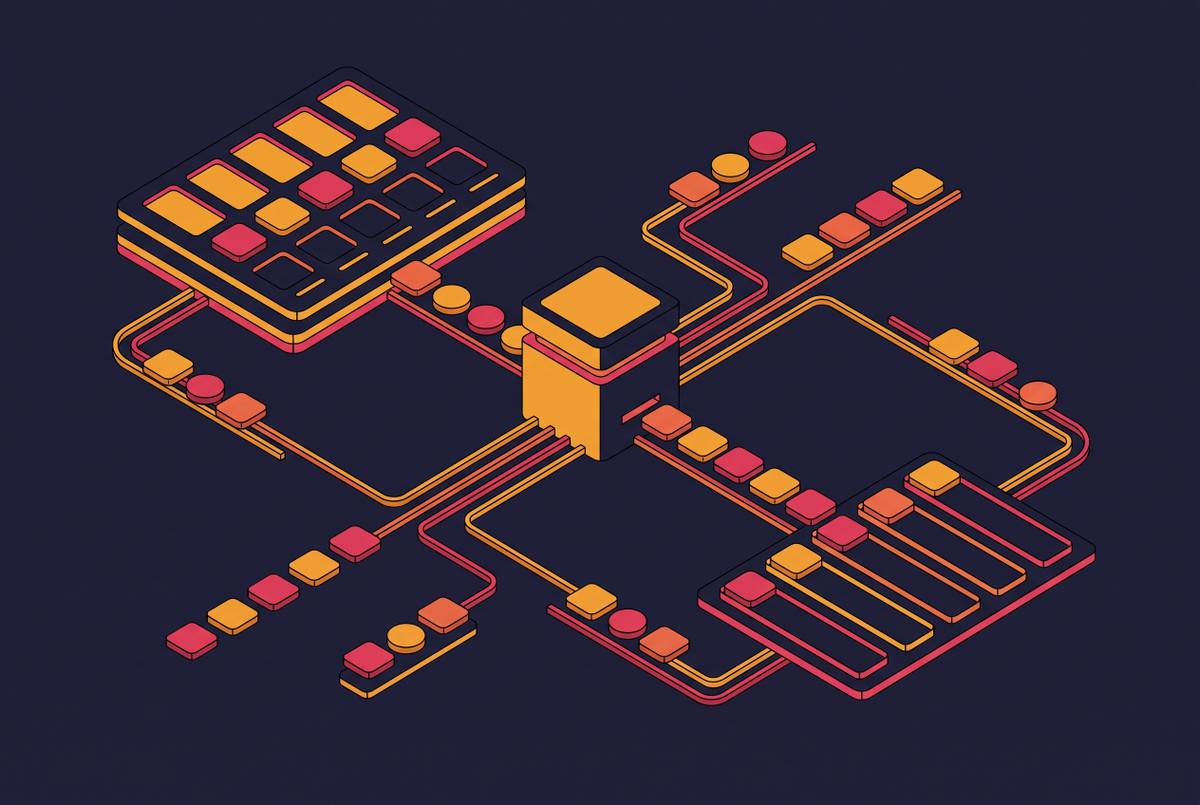
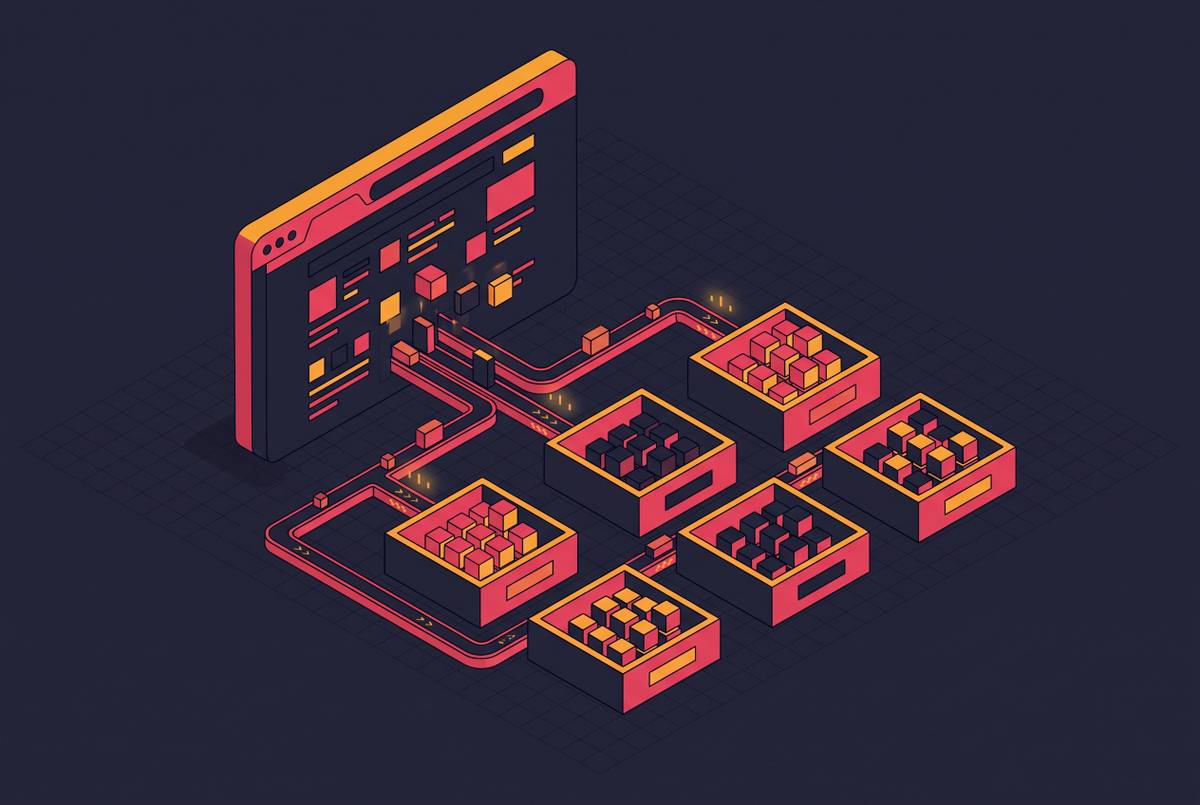
The traditional setup is easiest to picture as several separate feeds converging on a normalization layer. Page content comes from a website scraper, firmographics from a LinkedIn data tool, technology signals from a technographic provider, and visual identity from a logo or brand API. Custom code then reconciles their formats and conflicting values before anything reaches the CRM. Each connector brings its own authentication, rate limits, failure modes, and update cadence.
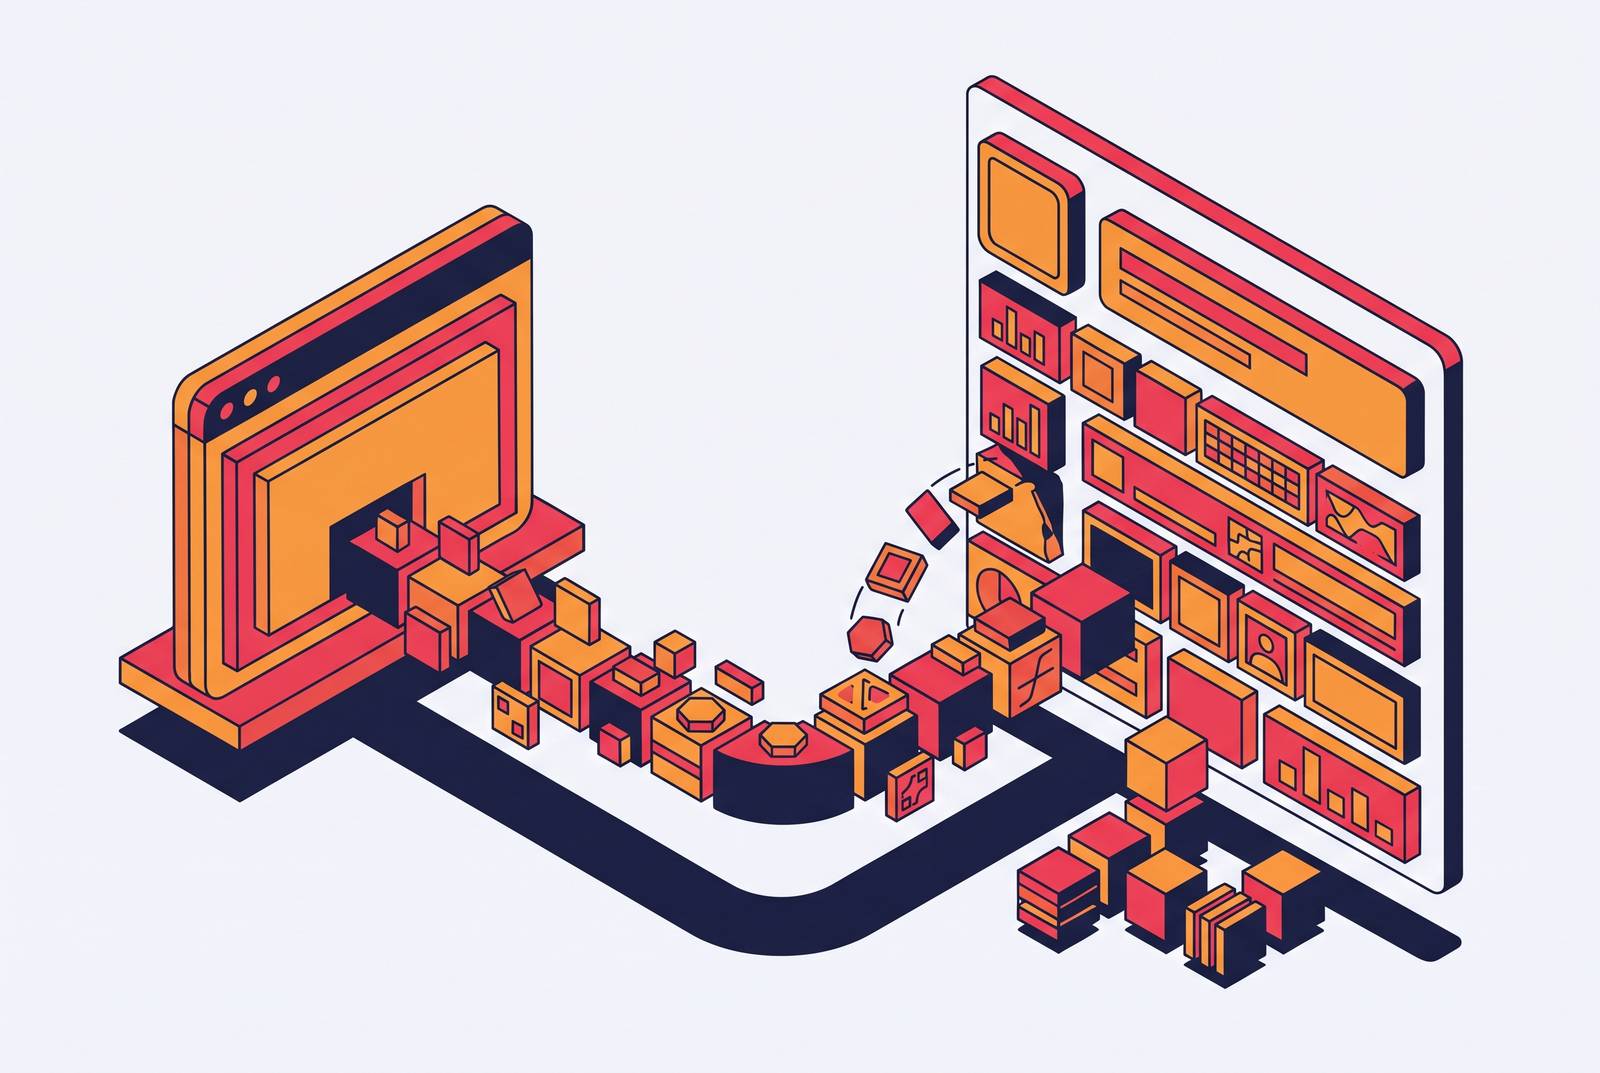
The alternative is a domain-in, JSON-out flow for fields supported by public website content. Instead of specifying where every value sits on every page, the developer sends a URL and a JSON schema describing the desired output. The extraction stage returns structured data for validation and direct mapping to CRM fields. The architecture shifts from assembling and normalizing feeds to defining a contract once and running it against live content when needed. That is what makes the process repeatable across sites with different layouts.
The scope of that replacement matters. Website extraction cannot take the place of intent data, human-verified contact databases, or conversation intelligence. Nor does it make every firmographic field available on a homepage. It replaces the fragmented collection and formatting work for the firmographic, technographic, and brand fields that public pages actually support.
The fields a prospect's own website can reliably populate
A company’s own site is the most authoritative source for how it describes its business, products, and customers. Its homepage can support a one- to two-sentence company description, a primary product or service category, and a target customer or industry vertical. Headquarters location and contact email are also available when the company publishes them. These fields cover much of what a go-to-market team needs to qualify and route a prospect. Even an authoritative site can be incomplete, so a missing location must stay missing.
The website also exposes information beyond its visible copy. Page source can reveal client-side scripting frameworks, analytics tags, chat widgets, and third-party integrations. Brand extraction can capture a logo URL, primary color palette, typography, and social profile links for products and onboarding flows to consume programmatically. These are distinct kinds of evidence, even when they come from the same domain. A pipeline that only reads homepage text cannot treat that text as a substitute for page-source or brand extraction.
Other fields need other sources. Employee count and headcount growth need data from a LinkedIn company page, while funding rounds and investor data need Crunchbase or a source like it. Verified decision-maker details need to come from providers that specialize in contact data. Job postings give a different signal, since hiring a Head of Security can point to a fit for security tools, while hiring Data Engineers can point to spending on data infrastructure.
How to define the JSON schema that drives extraction
Schema design starts with the CRM field map. Define fields according to what the receiving system needs to accept. A minimal JSON schema defines an object with five properties, namely description, product, target_customer, location, and email. Each property holds a string when there is evidence for its value. For a pipeline that preserves partial records, each property also needs to permit null when its value cannot be found.
That small schema is a contract. It fixes field names and types so the extraction result has a predictable destination. Where the CRM expects a category, such as an industry vertical or company stage, an enum constrains the output to accepted values. With free-form text in those fields, a later stage would still have to do the normalization work.
Required fields need similar care because record completeness and record usefulness are not the same thing. Make a value mandatory only when its absence should reject the record. For high-volume runs, a record with supported values and nulls is usually preferable to a dropped record. Keep brand fields in a nested brand object so logo URLs, hex colors, font families, and social links remain available to the product interface without cluttering the flat CRM field map. When qualification criteria change, keep a new version of this schema with the pipeline code.
The end-to-end pipeline: from domain input to populated CRM record
Read the pipeline from left to right as URL normalization, content fetching, schema-driven extraction, validation, supplementary enrichment, and CRM write. Each boundary makes clear what goes into the next stage and makes it easier to find where things failed. The first stage accepts a raw domain or company name and resolves it to a canonical homepage URL. Redirects and www variants belong here, before the content fetch. Without that boundary, later stages inherit uncertainty about which page they are supposed to process.
The fetch stage retrieves the content needed for extraction. Static sites can be fetched directly, but sites that rely heavily on client-side scripting need a headless browser to get rendered HTML. Convert that HTML to Markdown before sending it to the language model to reduce token use and keep inference costs more predictable. Page-source technology signals still need their own collection path because they are not the same as readable page content.
The extraction stage receives the Markdown and the JSON schema together. Its instruction is to return only fields supported by the page and use null for values it cannot locate. Validation then checks the returned JSON against the schema and flags missing high-value fields such as description or location. Completeness can serve as a routing signal, sending complete records straight toward the CRM and incomplete ones to a secondary enrichment pass.
Supplementary enrichment supplies employee count, funding, or decision-maker data from the appropriate sources. Those fetches can run in parallel before the merge, with the website result providing the core profile. The CRM write then maps validated properties to the destination field names. Write only non-null values so a failed extraction does not erase good data that is already there. Log the extraction timestamp in last_enriched_at, which gives the freshness process a concrete starting point.
Where extraction breaks and how to handle it in production
LLM extraction adds per-page inference cost and latency that selector-based parsing does not. For high-volume, uniform sources, selectors win on cost, and there is no reason to hide that trade-off. B2B company profiles present a different workload because the sites vary and enrichment volumes are lower than bulk, uniform scraping workloads. In that setting, avoiding continual parser maintenance can outweigh the model bill. The relevant comparison is total cost of ownership.
Reserve the model for fields that require meaning to be interpreted, including the company description, product category, and target customer. Use cheaper selectors or regex extraction for structured values that sit in known places, such as email addresses, social links, and phone numbers. The Markdown conversion in the fetch stage further reduces the material the model must process.
Reliability takes more than valid JSON because a fabricated location can still be a valid string. Explicitly instruct the model to return null unless a value appears verbatim or follows by clear implication from the page. Treat every non-null result as a claim that needs a basis in the supplied content. Cross-check locations against a known-good geographic lookup. Flag suspiciously long or generic descriptions for human review. Schema validation checks the shape of the answer, while these checks address its substance.
Semantic extraction does not depend on a fixed DOM position, so moving an About section does not by itself break the extraction. But a model cannot interpret content that the fetch stage never obtained. Bot detection can block a pipeline that relies on direct requests from a single IP at scale. Managed fetch infrastructure can handle proxy rotation, header normalization, and retries below the extraction stage, so failures to get content stay separate from failures to interpret it.
Keeping profiles fresh as companies change
A populated record is still only a snapshot. Contact and firmographic data decay over time, so a profile created when a deal opens may be wrong by the renewal conversation. Use last_enriched_at to find records older than a chosen threshold and queue them during off-peak hours. As part of that process, check whether the source has changed before paying to extract the same content again.
A homepage content hash, meta description, product tagline, or CTA copy can signal that the core profile needs another pass. Changes in those elements can make the description, product category, or target customer stale. But a homepage that has stayed the same says nothing about fields that came from another source. Technology signals also need a separate, more frequent crawl of page source because a company can add or remove a tool without changing visible text. Freshness should follow the evidence each field depends on, rather than one blanket schedule for the whole record.
The implementation reuses the schema already defined. At the request level, a request to the extraction endpoint carries the domain and that schema, with API key authentication supplied through a token query parameter and JSON returned for validation. When the homepage lacks the necessary evidence, crawling can follow internal links to pages such as About or Customers and aggregate their content before extraction. SchemaFlow describes a unified API, but its rendering, Markdown, extraction, and brand capabilities span separate endpoint products, so a shared interface should not be confused with a single all-purpose endpoint.
The refreshed result then passes through the same validation and non-null CRM write rules as the initial extraction. That continuity keeps refresh from becoming a second, less controlled way to modify records. The same freshness logic applies when the CRM feeds a pipeline that retrieves information to support generated responses. The essential pattern remains narrow and practical, with a schema defining what counts as a profile and source changes determining when to rebuild it. Automatic population works when it is treated as a repeatable data process.