Gating Feature Releases on Web Data Quality Metrics
Enforcing data quality checks prevents bad web data from corrupting AI predictions at scale.
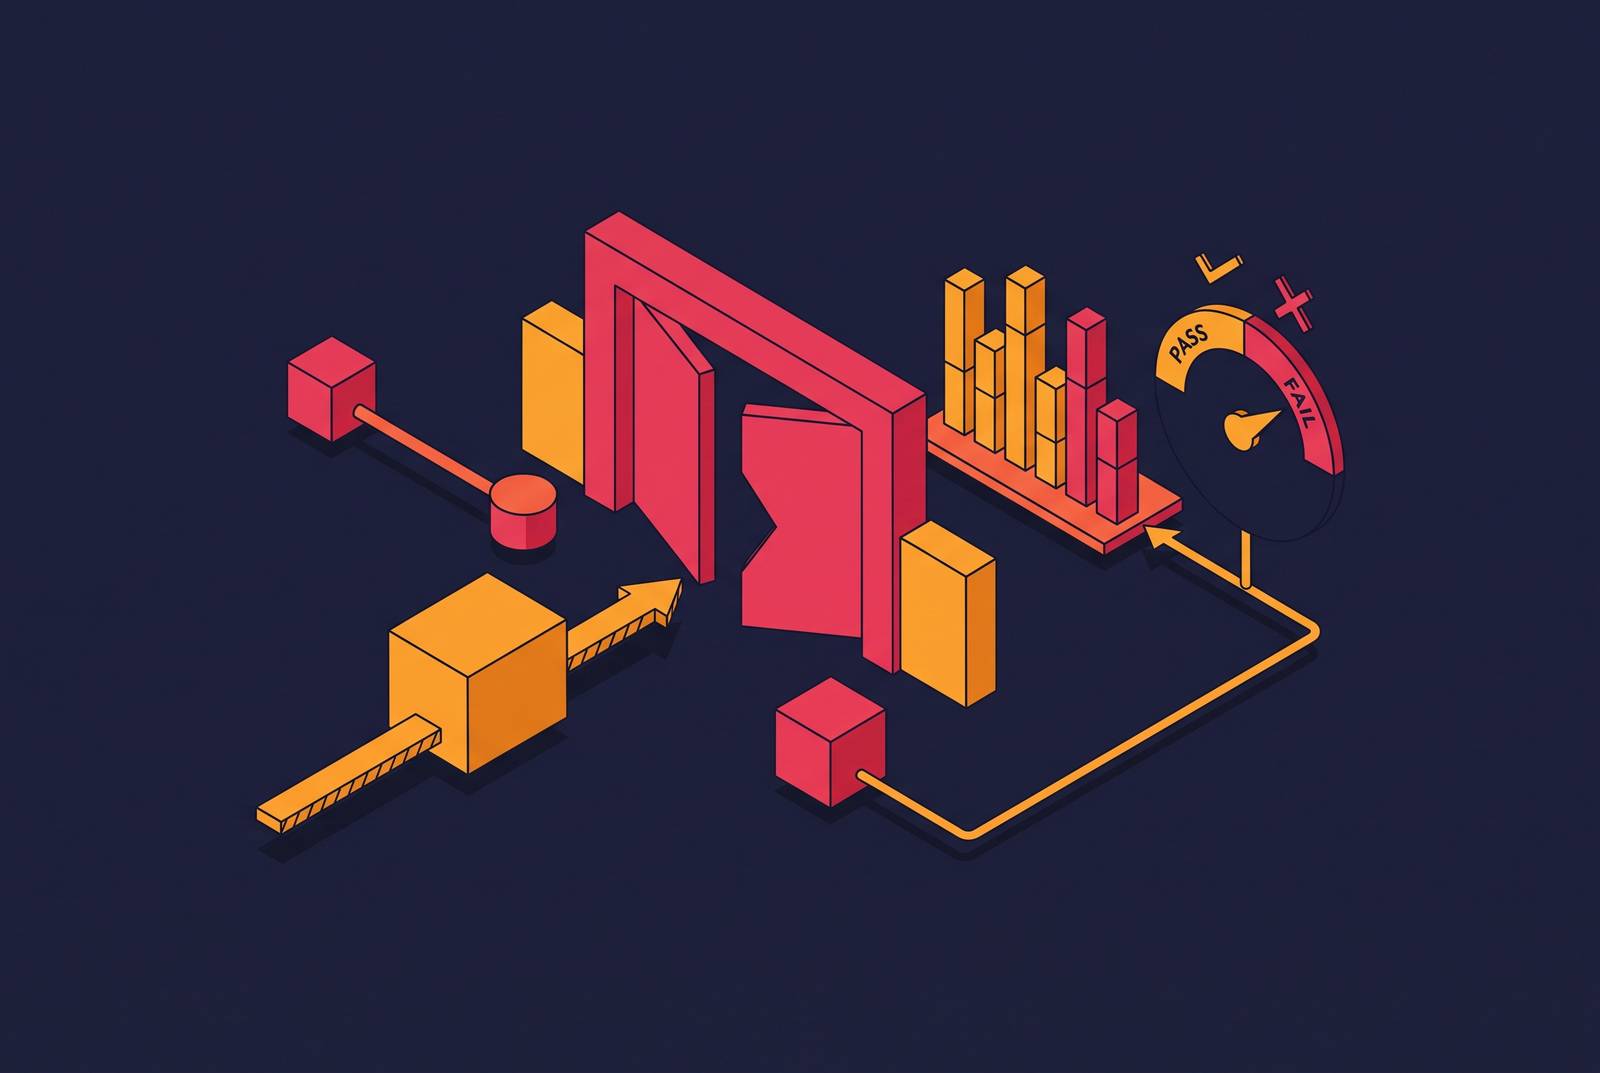
AI features grounded in live web data need release gates for both their data and their code. A green build does not show whether a scraped page is up to date, has all its content, or is even the page that was requested. The release rule is simple. Define what usable web data looks like, test it at every handoff, and stop failed data before the feature acts on it.
Why AI features built on live web data need a different kind of release gate
When a test fails, the CI/CD light turns red and nothing ships. When a scrape fails, that light can stay green while the model keeps making answers from empty fields, stale pages, or broken extraction. The software still runs, so the failure looks like success. That is why a code-only release gate leaves a serious gap.
The gap grows when each stage in the pipeline trusts everything that came before it. Bad data travels downstream without a checkpoint, and an AI feature can repeat the same bad pattern across millions of predictions at inference speed. Live web sources make this harder because the team does not control them. Pages change, sites block crawlers, and fields can vanish with no warning. The pipeline needs clear rules to catch those failures.
What a data quality gate actually is and how the write-audit-publish pattern works
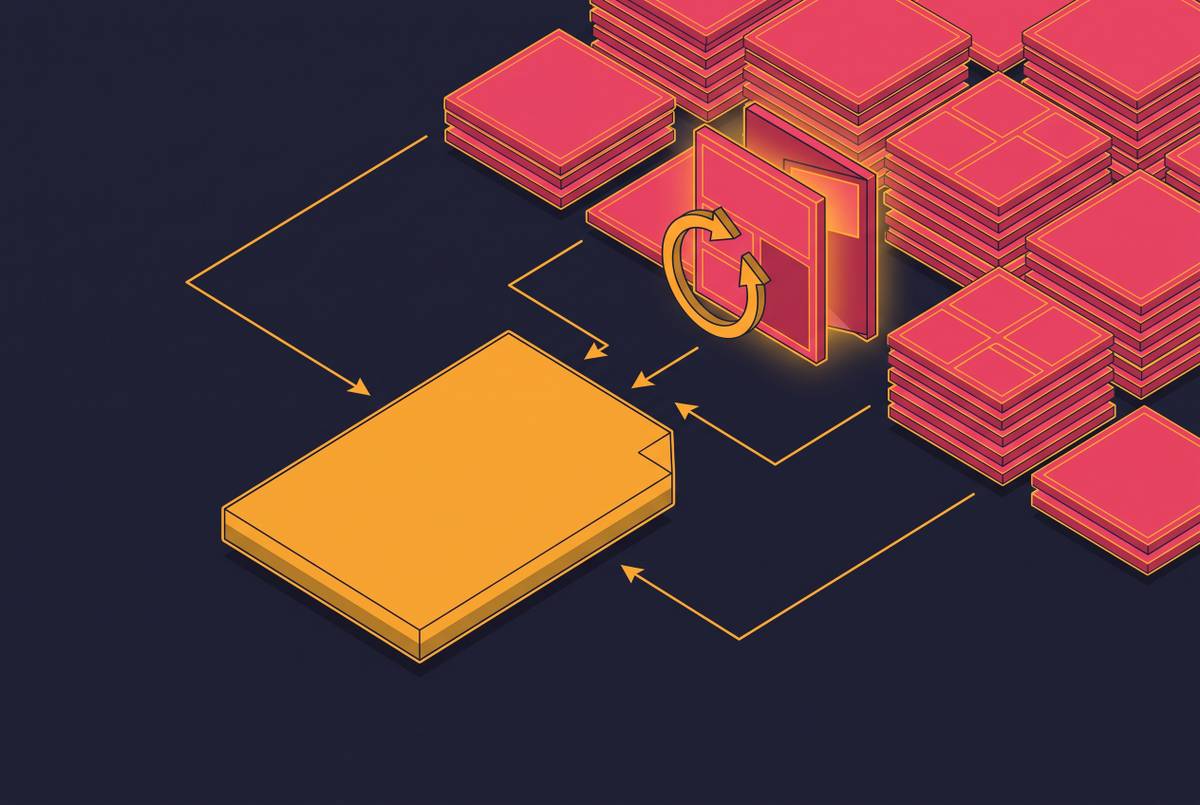
A data quality gate is a machine-enforced checkpoint that holds incoming data until it passes defined checks. The write-audit-publish pattern gives that checkpoint a safe place to run. First, the batch lands in staging, where downstream consumers cannot read it. Next, the audit checks the batch that is in staging. If the required checks pass, the data swaps atomically into production.
If a blocking check fails, the batch stays in staging, the pipeline turns red, and an alert fires. The failed data remains exactly as it arrived for debugging. This is the data equivalent of deploying to staging, running smoke tests, and then flipping traffic. Block means the data is unusable, while Warn means it is suspicious but usable.
A concrete implementation can run Soda Core checks in Tekton. Rules such as row_count > 1000 and missing_count(customer_id) = 0 make the acceptance criteria explicit. Neither rule is complicated. The value comes from running the audit automatically on every batch, rather than relying on someone to notice a problem afterward.
Why web-sourced data demands quality dimensions that traditional pipelines never had to measure
Traditional checks cover six dimensions, which are accuracy, completeness, consistency, timeliness, validity, and uniqueness. AI data from the web also needs checks for noise ratio, distribution drift, representativeness, and, when extraction uses ground-truth labels, label accuracy. These checks address failures that can leave a dataset looking populated while making it unfit for the feature.
For example, raw HTML feeds navigation menus, cookie banners, and inline styles into a chunker, while clean Markdown removes much of that noise and preserves document structure. Format is therefore an input to the gate. Chunking must also respect document boundaries. A large response is not necessarily a useful response.
A redesign can move fields away from their selectors, while a partial crawl can miss newly added sections and stop representing the live source. Structured extraction can also return a field that exists but means the wrong thing. These checks matter after training too, because inference data must still fit the model’s assumptions and feedback from production needs to flow upstream.
The five metric families that web data gates should enforce, and the 2026 benchmarks for each
The practical checks fall into five families, which are Volume, Completeness, Freshness, Validity, and Uniqueness. Treat the 2026 benchmarks as directional targets. Some checks have numerical targets, while others need a limit defined by the feature’s requirements. Writing down those limits is part of building the gate.
Volume checks whether about as much content arrived as was expected. A blocked crawler may return zero rows or a single error page, so a batch below the defined minimum is a Block. Completeness checks whether the required fields are filled in, with a target null rate under 2% for critical fields. That aggregate target does not excuse a missing required field, which remains a Block.
Freshness asks whether the content is recent enough for its use. Its threshold must follow the feature’s freshness SLA. Validity checks allowed types, ranges, and values, including whether a URL is canonical. For structured extraction with ground-truth labels, a low label error rate is also relevant.
Uniqueness catches the same canonical page indexed under multiple URLs, with a target duplicate record rate under 0.1%. Measure mean time to detect and mean time to resolve as well. Those speed measures show whether the gate catches problems promptly and whether operators can clear them.
Where web data quality gates live in an AI feature pipeline: the four handoff points
Gate 1 belongs at raw fetch, before the pipeline trusts the content in an HTTP response. It checks for an actual page rather than an error response, CAPTCHA wall, or redirect chain. Volume and validity matter here, but so does usable signal. A response with 80% navigation markup can pass a size check and still be poor input.
Gate 2 belongs at structured extraction, where the returned JSON must satisfy the developer-defined JSON Schema. Required fields, types, and values form the contract at this boundary. The gate catches schema drift and extraction hallucinations on malformed pages before they become downstream records.
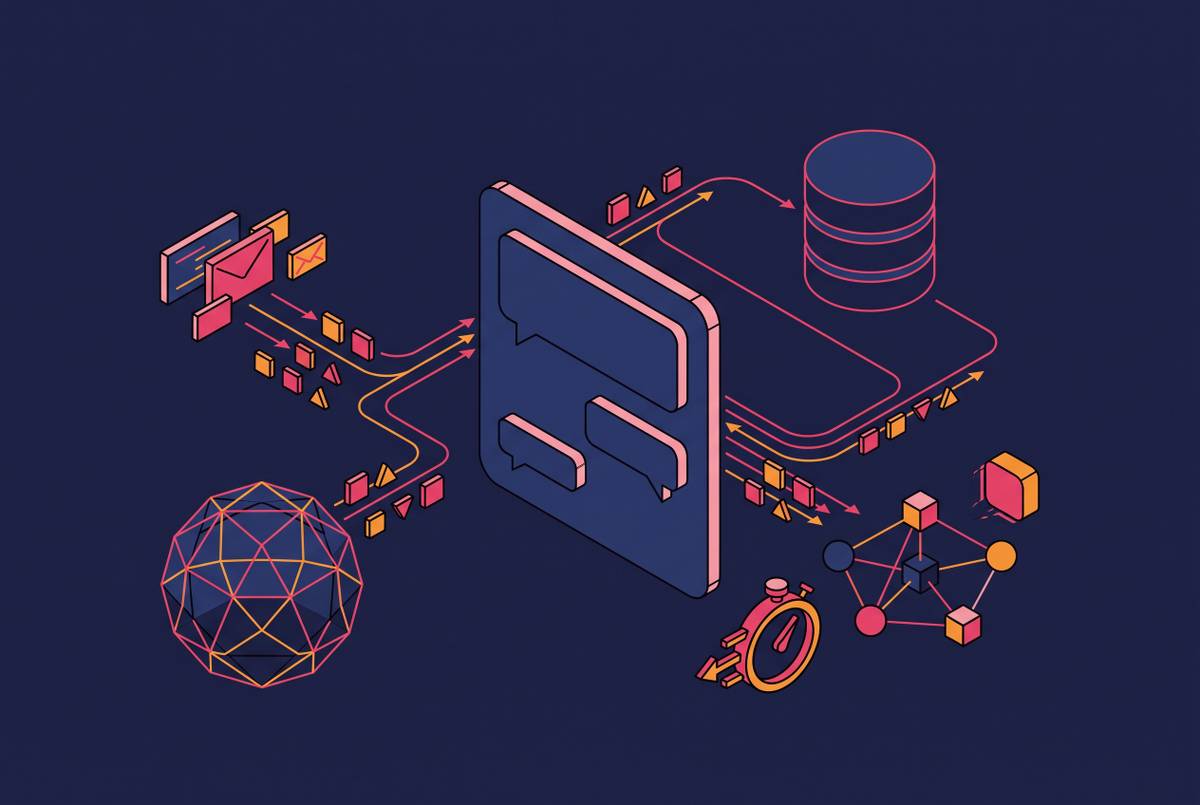
Gate 3 runs before embeddings go into a vector store or features go into a feature store. Freshness and uniqueness checks stop stale or duplicate content from entering the index. Gate 4 runs at production inference, where distribution checks test whether the data coming in still fits what the model was trained on. When drift is significant, the team needs to look for changes upstream.
Each handoff also needs provenance metadata, including the source identifier, extraction timestamp, preprocessing script version, and model version. Store that lineage in a queryable form. When quality degrades, the team needs to trace the affected artifact back to its origin.
Change detection as a continuous gate trigger, not a human notification
A gate that runs only when someone starts a pipeline does not cover a live source between runs. Changes to a source that matter to the feature need to trigger re-crawling and validation. Third-party API documentation makes the case clear. A deprecated endpoint matters when the documentation changes, before the integration breaks.
The monitoring options serve different needs. Visualping supports visual screenshot diffing as well as text, element, and combined monitoring modes. Distill.io is browser-extension-first and offers local, in-browser monitoring. Fluxguard focuses on compliance and enterprise use, with generative AI to filter and summarize changes. changedetection.io is open-source and self-hosted, while another monitoring tool supports multiple detection types, including tech-stack changes.
Pixel and exact-text comparisons can flag rotating ads, timestamps, cookie notices, and layout shifts that have no bearing on the feature. Semantic diff adds a relevance filter before the gate fires. An LLM judges whether a detected change matters against a description of what the pipeline is watching for. That can distinguish a newly announced product from a rotating testimonial without treating every page edit as a release failure.
How schema-driven structured extraction changes what "passing" a gate means
CSS selectors and XPath describe where to find content, but they are brittle when a site redesigns. Schema-driven extraction spells out what the result should contain. An extraction API can accept a developer-defined schema and return validated JSON. The schema becomes the contract between the extractor and the pipeline.
The gate can check types and allowed ranges, then use a lightweight LLM check to test whether a value matches the field’s description. A promotional string in a numeric price field fails the type requirement. A value with the right type but the wrong meaning needs the semantic check. Schema-aware extraction does not remove the need for an audit, and schemas and gates must evolve together as target pages change.
Brand profiles make the distinction concrete. An endpoint may return logos, colors, a description, an address, industries, and social links for a domain. A feature that renders brand assets cannot treat a missing logo URL or null color palette as a successful result. Those required fields are part of the release contract, so their absence is a Block.
Agentic AI pipelines and why the gate must move to the tool-call layer
An autonomous agent goes through observe, plan, and act in the same run. If observation returns bad web data, the agent can act on it before a batch-level audit fires. The gate therefore has to sit at the tool-call boundary, before the response becomes evidence for planning. A downstream index check is still useful, but it arrives too late for that immediate decision.
For example, an agent looking into a public company may get a generic security challenge in response to its page request. The API layer must handle browser fingerprint normalization, or the gate must recognize the challenge response and block the act step. A completed request is not enough. The response must contain usable evidence.
The same principle applies to schema failures across tool calls. Observability needs thresholds tied to quality metrics, with circuit breakers that stop faulty records from being written downstream. Continuous checks matter because the agent does not wait for a human to inspect each result. The faster the loop, the closer the gate must be to the observation it controls.
The gate-fatigue problem and how to calibrate severity without overriding your own pipeline
Aggressive gating fails when operators learn to override it. Keep checkpoints and separate unusable data from data that deserves attention. Use Block when batches are empty, required fields are missing, schema types are invalid, or the pages are challenge or error pages. Use Warn when the data is still usable but has a suspicious value, a small dip in volume, or freshness within a defined grace window.
Those distinctions need explicit boundaries. A hard minimum is not the same as an expected volume, and an invalid value is not the same as an unusual one. Logging Warns keeps the pipeline moving and leaves an audit trail of where data quality may be getting worse. Semantic diff cuts more noise by checking changes against a clear description of what matters.
Infrastructure choices affect who does that tuning. With self-hosted changedetection.io, teams have control but must handle proxy rotation, rendering, and false-positive tuning themselves. Managed API-first stacks absorb that work so teams can focus on quality rules. Neither choice removes the need to define severity.
Include the exact failed check, the offending values, and a suggested remediation path.
Putting it together: a release checklist for AI features that consume live web data
Release readiness starts with an enforced contract at every handoff. At raw fetch, require the expected minimum of usable content, block challenge-page responses, and check whether the formatting leaves too much noise. Confirm that browser fingerprint normalization and proxy rotation are handled at the API layer. At extraction, block missing required fields and type mismatches, then distinguish isolated semantic anomalies from systematic failures.
Before index or feature ingestion, check canonical duplicates and enforce the freshness window. Features that need timely data need a Block on stale content, while content that changes more slowly may call for a Warn. Use write-audit-publish to keep data that fails out of the production index. At inference, alert and escalate on significant distribution drift.
The release evidence must also show what the feature acted on. Queryable lineage should identify the source URL, fetch timestamp, extraction schema version, and pipeline version behind the grounding data. Every external source needs a watch that triggers re-crawling and validation on meaningful change. Calibrate structural schema changes as Block and ordinary content updates as Warn so the watch remains useful.
The final test is whether the team has written down what healthy data means before shipping. Tools enforce that definition, but they cannot replace it. A feature is ready when bad web data gets the same clear red light as bad code.