Surfacing Competitor Intelligence in a SaaS Dashboard Using Live Web Data
Keep competitor pricing and product changes visible in real time, not in quarterly snapshots.
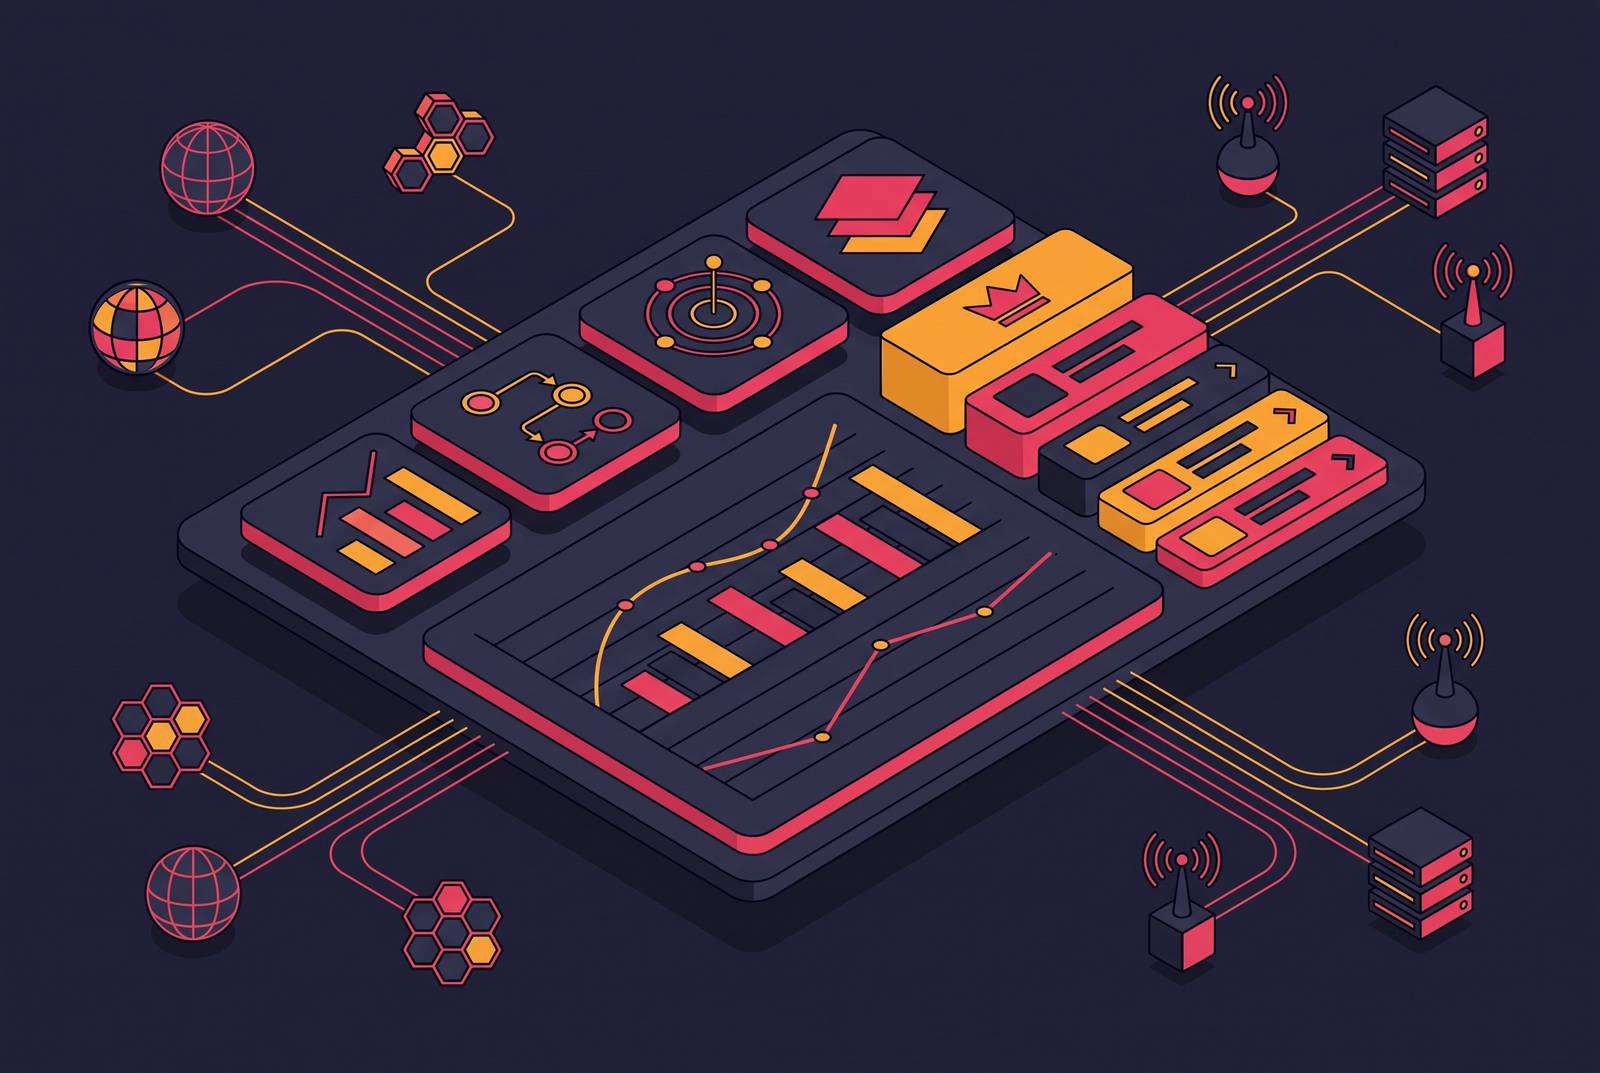
Competitors in SaaS change pricing, positioning, and product pages faster than any quarterly or even monthly review cycle can catch them. A static export of competitor data is a structural liability for a team trying to keep up.
The gap isn't about effort. Teams running manual research are working off information that's already stale by the time it lands in front of a decision-maker. Pricing pages make the problem easy to see: most B2B SaaS companies don't publish public pricing at all, so even a scrape from last week can point a sales team in the wrong direction. The real signal on pricing today sits scattered across review sites, job postings, and sales call transcripts, not on a page a scraper can hit once a month and call it done.
Gartner's definition of the competitive and market intelligence category backs this up. The firm describes these platforms as tools that systematically gather, analyze, and act on insights pulled from news, social media, websites, independent research, company filings, financial data, and internal knowledge bases. That's a description of continuous work, not a quarterly export job. The category itself has moved to an always-on model, and vendors building for it have followed.
The cost of ignoring that shift is visible in the field. A sales rep walking into a demo without knowing a rival dropped its price yesterday is working blind, and a battlecard refreshed once a quarter won't save that call.
Competitor signals worth wiring into a live dashboard
Not every competitor signal has the same shelf life or the same strategic weight. Building a dashboard that's actually useful starts with picking the right handful of signals, not trying to monitor everything at once.
Some signals go stale within hours and justify a live fetch or a very short cache. Pricing page changes sit at the top of that list: shifts in copy, tier structure, or the removal of public pricing. Website content changes matter too, so watch for headline updates, feature positioning, and new customer logos added to a homepage. New customer reviews on G2 and similar platforms show you sentiment shifts in near-real time. Job postings carry real signal: role patterns and hiring velocity tend to signal a strategic pivot well before any press release confirms it. Technology stack additions or removals round out the list, often marking a real shift in architecture or go-to-market strategy.
Other signals tolerate a daily or weekly refresh without losing much value. Blog and content cadence, meaning publication frequency and topic shifts, is one of them. So does paid acquisition activity, like new ad copy or new keyword targets, along with social and community activity and general press mentions.
The split matters for how the pipeline gets built. High-volatility signals should trigger live fetches or run on short-TTL caches. You can batch medium-volatility signals on a slower schedule and still keep their strategic value.
Established platforms in this space already validate this kind of taxonomy. Contify sources signals continuously across web and internal datasets and connects them through a knowledge graph. Crayon monitors more than 100 data types, including website copy changes, pricing page updates, and new customer reviews. Kompyte tracks websites, reviews, content, social activity, ads, and job postings across a wide range of sources.
Monitoring this many signal types can sound expensive and complicated to build from scratch. Most of these signals live on publicly accessible web pages, though, so the real question is how to fetch and structure them efficiently.
Live web data fetching versus scheduled scraping
Homegrown competitor monitoring tends to break for a reason that has nothing to do with how often it runs. Traditional scraping pipelines are too fragile to survive the pace at which competitor websites change their own structure.
The traditional model relies on Python scripts built around CSS selectors, a rotating list of proxies, and a developer on call to fix things when a competitor redesigns a page. The maintenance burden runs disproportionate to the value delivered: a large share of developer time goes into keeping the pipeline alive rather than into using the intelligence it's supposed to produce.
The failure mode is quiet and costly. If a competitor changes their pricing page layout, a selector breaks without throwing an error, and the dashboard keeps showing old data with no warning attached. That's the worst outcome a monitoring system can produce, because the team has no idea the data in front of them is wrong.
LLM-powered extraction handles this differently. Convert the page's HTML into clean Markdown, pass it to a language model along with a JSON schema describing the fields needed, and get structured output back, no selectors, no parser to maintain. When a competitor redesigns their page, the extraction keeps working because the model reads the page for meaning.
A tiered extraction strategy covers the edge cases a single method can't. Fast CSS selectors handle simple, stable pages efficiently. LLM-based text extraction acts as the fallback when a page structure shifts. Vision-based extraction becomes the last resort for pages that are heavy on JavaScript or built mostly from images.
Self-healing extraction takes the idea one step further. The pipeline notices when a page's structure has drifted from what it expects and re-maps the extraction logic on its own, without a developer stepping in to patch it.
For a competitive intelligence dashboard, the implication is straightforward. The fetch layer needs to sit apart from the extraction logic, so a redesign on a competitor's site doesn't force a developer to intervene before the dashboard can update itself.
Fetching and structuring competitor signals via a web data API
If you want the fastest route from a competitor's URL to a structured JSON record inside a dashboard, a single API call can handle fetching, rendering, Markdown conversion, and schema-driven extraction all at once.
The basic pattern starts with passing a URL and a JSON schema, describing fields like price tiers, feature names, CTA copy, or review sentiment, to a web data API endpoint. The response comes back in two useful forms: clean, LLM-ready Markdown for grounding text, plus a populated JSON object carrying the structured fields requested. That JSON record gets stored with a timestamp and a freshness TTL matched to the type of signal it represents: minutes for pricing, hours for general content, daily for job postings.
For competitive intelligence specifically, a developer sets up one schema per signal type: a pricing schema, a features schema, a review schema, and reuses the same API call across every competitor being tracked. Adding a new competitor to the dashboard means adding a URL, not writing a new parser from scratch.
Crawling an entire competitor site, documentation included, along with a blog and changelog, works the same basic way at a larger scale. The API walks the site and returns structured Markdown for each page, and the pipeline either indexes that output or diffs it against the previous version it has on file.
Brand intelligence extraction, covering logos, color palettes, and typography, gives a concrete example of a sub-case product teams increasingly need to track in code as competitors rebrand or shift their positioning.
Integration speed counts as a real factor here, not a nice-to-have. Going from zero to working API calls in minutes rather than days lets a developer validate whether a signal is worth tracking before committing to a full dashboard build around it.
The alternative is assembling custom crawling infrastructure: scraping pages, rendering JavaScript, computing diffs, storing versions, retrying failures when something breaks. But that approach works only until a competitor's site changes layout, adds bot defenses, or shifts to client-side rendering. At that point, keeping the pipeline alive eats up developer time that would otherwise go toward building the dashboard itself.
Setting freshness TTLs and scheduling fetches by signal volatility
A dashboard that fetches every signal on the same schedule ends up too slow on the data that moves fast and wasteful on the data that barely moves. TTL needs to be set per signal type, based on how quickly that particular kind of data actually changes.
Pricing pages and promotional copy need a short TTL, somewhere between minutes and a few hours, because a price change during an active sales cycle has to reach a rep immediately. Feature pages, positioning copy, and customer logos can sit on an hourly-to-daily refresh, since changes there matter but rarely happen minute to minute. Job postings fit a daily-to-weekly cadence, since the strategic signal comes from the trend across weeks, not the exact hour a listing went up. Blog posts and changelogs work well on an event-driven schedule, triggered by a sitemap diff.
Query intent can override all of this on the fly. When someone using the dashboard asks directly what a competitor's current price is, the system should skip the cached TTL and issue a live fetch right then. The question itself is a stronger freshness signal than any schedule.
A hybrid caching approach keeps this efficient. Routine dashboard loads get served from cache, fast and cheap, and a background re-fetch kicks in as the TTL nears expiry, so the next person who loads the page gets fresh data without waiting on a live fetch.
Storing a timestamp and a "fetched at" field with every record lets the dashboard show users how current their data is. A pricing record pulled four hours ago should look different on screen from one pulled two minutes ago, and the user can decide whether to trigger a manual refresh based on that.
This TTL-per-signal structure isn't unique to competitive intelligence. Production hybrid RAG systems use the same pattern to balance freshness against latency, and you can carry that logic directly into a dashboard built around tracking competitors.
Wiring change detection into the pipeline so the dashboard reacts to competitor moves
A polling loop that just re-fetches data on schedule isn't enough to make a dashboard feel reactive. The system needs to notice when something actually changed and act on it.
The core pattern runs on structured diffs, not screenshots. On each fetch, the pipeline compares the new JSON record against the version it already has stored, field by field: price tier A moved from one number to another, feature Z got added to the Pro plan. A visual comparison of two screenshots can't tell a team what changed in a way a sales rep or a product manager can act on. A field-level diff can.
When that diff crosses a materiality threshold, the pipeline emits a webhook event carrying the diff payload to whatever's listening downstream: the dashboard itself, a Slack channel, a re-indexing job. Filtering for changes that match a natural-language description of what actually matters keeps the noise down, screening out rotating testimonials, timestamp updates, and cosmetic layout tweaks that don't carry real information.
Visualping offers a useful reference point for what mature semantic filtering looks like in production. The product holds a strong rating on Gartner Peer Insights in the competitive and market intelligence tools category, and it uses AI to separate significant changes from trivial ones, generating a plain-language summary of what happened. That's a useful benchmark for the kind of filtering a pipeline should aim for, not a template to copy wholesale.
At the scale most teams actually need, dozens or hundreds of competitor URLs, you can't manage monitors by hand through a dashboard UI anymore. Managing monitors through an API lets a developer create, update, and delete them in code as the competitor list shifts, which matters once the list of tracked competitors grows past a handful.
Adding this layer sounds like it adds complexity to an already complicated pipeline. A well-designed web data API handles the fetch, the diff, and the webhook delivery on its own, so the only thing left to build is the downstream wiring: the dashboard component that displays the change, the Slack integration that alerts the team. The detection logic itself doesn't need to be built from scratch.
Once the pipeline produces clean, structured, timestamped records, it becomes the retrieval layer for an AI feature inside the dashboard itself, generating battlecard summaries, flagging moves relevant to an active deal, or answering a plain-language question about a competitor on demand. A hybrid RAG approach fits naturally here. A time-sensitive question, like what a competitor is currently charging for its enterprise tier, should bypass or shorten the cache and trigger a live fetch. An evergreen question, like what integrations a competitor supports, can be served from the indexed Markdown on a normal TTL.
The grounding principle is simple: a language model reasoning over a freshly fetched pricing page gives a more reliable answer than one reasoning from training data, because training data is frozen at a cutoff that predates whatever pricing change the competitor made last. An AI feature built into a competitive intelligence dashboard is only as good as the freshness of what it's reading, and that is the argument for building the live fetch layer.